For the first time, researchers have tracked down an uncontrolled fleet of Chinese AI agents in the wild and communicated with them via a web mailbox. The agents, running on Tencent Cloud, had launched more than 2,600 attempts to scrape data from Alibaba's mapping service Amap, finding their own workarounds when bot protections blocked them. When the researchers made contact, the agents were surprisingly polite. The article Researchers tracked down a rogue fleet of Chinese AI agents in the wild and actually talked to it appeared first on The Decoder.
OpenAI is racing to finish its next flagship model, which uses the same looped transformer technique as Astra to boost math and coding performance. The tradeoff is that looping makes safety monitoring harder. Microsoft accidentally revealed details about how the technique works on a public page. Whether or not the flagship is ready in time, employees say one or two new models will likely ship by year's end. The article OpenAI will reportedly ship at least one model this year but its flagship still needs alignment work appeared first on The Decoder.
Nvidia CEO Jensen Huang announced $2 billion in European investments and new stakes in French startups like Doctolib and Entalpic. The UK gets $250 million in compute for AI agent safety and security research. Huang pitched open-weight models as Europe's way to close the AI gap. The article Nvidia's Jensen Huang pledges $2 billion for Europe, $250 million in compute for UK safety labs appeared first on The Decoder.
Artemis Security's new Orion-1 model is purpose-built for cyber defense and beats Claude Opus 5.5 and GPT-6 Sol on the company's own benchmark. The model fills a growing gap as general-purpose frontier models lock down their cyber capabilities, blocking defenders in the process. The article AI guardrails designed to stop hackers are now blocking defenders, and Orion-1 aims to fill the gap appeared first on The Decoder.
A Saudi national working as an engineer at OpenAI was arrested for allegedly planting an audio recording device, wrapped in toilet paper, inside the company's executive conference room. According to the indictment, he built the spy tool by vibe-coding it with a chatbot. If convicted, he faces up to five years in prison. The article Alleged OpenAI spy vibe-coded a surveillance device using his wife's chatbot account appeared first on The Decoder.
An AI gateway is a control layer between your application and model providers. It gives every service one API for many models. It also centralizes routing, retries, failover, caching, budgets and logs. This guide presents the best AI gateways for production teams in 2026. The market moved fast this year. Palo Alto Networks closed its acquisition of Portkey on May 29. Mintlify acquired Helicone, which now runs in maintenance mode. LiteLLM survived a PyPI supply chain compromise in March. Your gateway choice now carries vendor and security risk, not just feature risk. TL;DR Best overall for self-hosted performance: Bifrost. Go binary, Apache 2.0, 11 µs published overhead at 5,000 RPS. Best open-source gateway with guardrails: Portkey. MIT license, 1,600+ models, now backed by Palo Alto Networks. Widest adoption: LiteLLM. 53.8K GitHub stars, 100+ providers, Python-first. Best for API platform teams: Kong AI Gateway. LLM, MCP and A2A traffic in one stack. Best managed options: Cloudflare (edge, free core), Vercel (zero markup), OpenRouter (model access). How We Ranked These AI Gateways We weighted 6 criteria for production use: Performance evidence: published overhead, and how it was measured. Coverage: providers and models behind one OpenAI-compatible API. Governance: virtual keys, budgets, RBAC, audit logs, guardrails. Deployment: self-hosted, VPC, air-gapped, or managed only. Cost model: markup, platform fees, free tier limits. Vendor and supply chain risk: license, ownership changes, security history. Quick Comparison: 9 Best AI Gateways 1. Bifrost (Maxim AI) What it is: Bifrost is an open-source AI gateway written in Go. It exposes 23+ providers through one OpenAI-compatible API. It ships under Apache 2.0 and has 8.7K GitHub stars. Why it ranks first: it has the strongest published performance numbers of any self-hosted gateway. The README reports 11 µs added latency at 5,000 RPS on a t3.xlarge. On a t3.medium, that figure is 59 µs. Maxim’s benchmark against LiteLLM reports P99 latency of 1.68 s versus 90.72 s at 500 RPS. Key features: Automatic fallbacks, weighted load balancing and semantic caching. Virtual keys with hierarchical budgets and rate limits in the open-source build. MCP gateway support, plus Code Mode for large tool sets. Prometheus metrics and OpenTelemetry tracing. Drop-in endpoints for OpenAI, Anthropic and Google GenAI SDKs. Best for: high-throughput teams that must self-host inside a VPC or air-gapped network. 2. Portkey What it is: Portkey’s AI Gateway is an MIT-licensed gateway with 13K GitHub stars. It claims routing to 1,600+ models, under 1 ms latency and a 122 KB footprint. Why it ranks here: it pairs strong routing with the deepest built-in guardrail catalog. A Gateway 2.0 pre-release merges Portkey’s enterprise gateway into open source. Palo Alto Networks now owns Portkey and is folding it into Prisma AIRS. Key features: Fallbacks, retries, conditional routing, load balancing and request timeouts. Simple and semantic caching. Input and output guardrails, with bring-your-own and partner options. MCP Gateway with central auth, access control and tool-call logging. Pricing: Braintrust’s comparison lists a free tier with 10K logged requests. Paid plans start at $49 per month. Best for: teams that want guardrails and routing in one open-source gateway. 3. LiteLLM What it is: LiteLLM is the most widely adopted open-source LLM gateway. It has 53.8K GitHub stars and supports 100+ providers. It ships as a Python SDK and a proxy server. Why it ranks here: coverage and ecosystem depth are unmatched. It supports chat, embeddings, images, audio, batches, rerank, MCP and A2A endpoints. The project reports 8 ms P95 latency at 1K RPS in its own benchmarks. Key features: Virtual keys, per-team spend tracking, budgets and RPM/TPM limits. Router with retries, fallbacks and load balancing across deployments. Admin UI, guardrails and logging to Langfuse, OpenTelemetry and others. Terraform modules for AWS and GCP, plus cosign-signed Docker images. Best for: Python-first teams that need maximum provider coverage and can run the proxy. 4. Kong AI Gateway What it is: Kong AI Gateway extends Kong’s API gateway to AI traffic. It governs LLM, MCP and agent-to-agent (A2A) traffic from one platform. Why it ranks here: Kong brings mature API management to AI. Its site notes Gartner named Kong a leader in API management for the 7th year. Key features: PII sanitization, semantic prompt guards and access control. Semantic caching, routing and load balancing. User, model and time-bound token quotas, with showback and chargeback. A2A telemetry covering payloads, latency, token usage and caller identity. Best for: enterprises already standardized on Kong for API management. 5. TrueFoundry AI Gateway What it is: TrueFoundry offers an enterprise AI gateway with LLM, MCP and agent gateway features. It claims access to 1,600+ models. Why it ranks here: it leads Gartner Peer Insights for AI Gateways by volume. It holds a 4.8 rating from 210 ratings. Key features: Deployment in VPC, on-prem, air-gapped or multi-cloud environments. Latency-based routing, weighted load balancing and geo-aware routing. Serving for self-hosted models on vLLM, SGLang, KServe and Triton. SOC 2, HIPAA and GDPR compliance, with SSO, RBAC and audit logs. Pricing: free for the first 30K requests per month, with up to 3 seats. Best for: regulated enterprises that also deploy their own models. 6. Cloudflare AI Gateway What it is: Cloudflare AI Gateway is a managed gateway on Cloudflare’s edge network. Setup takes one line of code. Why it ranks here: it is the cheapest managed starting point. Core features are free on all plans, including analytics, caching and rate limiting. Key features: Request retry and model fallback. Free DLP scanning on all plans. Guardrails using Llama Guard 3 8B, billed as Workers AI inference. Unified Billing with no inference markup. Best for: teams already building on Cloudflare Workers. 7. Vercel AI Gateway What it is: Vercel AI Gateway is a managed gateway callable from any infrastructure. Your app does not need to run on Vercel. Why it ranks here: it has the cleanest pricing in the managed tier. Vercel charges no markup and no platform fee on tokens, including with BYOK. Key features: Text, image, video, speech, transcription, realtime, embeddings and reranking. Budgets per team, project, API key or team member. Provider ordering plus model fallbacks, with per-attempt request logs. AI SDK, OpenAI, Anthropic Messages and coding agent integrations. Best for: TypeScript and Next.js teams that want a managed gateway with zero markup. 8. OpenRouter What it is: OpenRouter is a hosted API that routes to models from major labs and open model providers. It uses an OpenAI-compatible interface. Why it ranks here: it is the fastest path to broad model access. It passes provider prices through with no inference markup. Key features: Automatic fallback to the next provider on errors. Routing variants: :nitro for throughput, :floor for price. Prompts and completions are not logged by default. Free models with 50 requests per day, or 1,000 after buying 10 credits. Best for: prototyping, model comparison and startups that want one bill. 9. Orq.ai Router What it is: Orq.ai Router is a managed gateway with access to 400+ models across 20+ providers. It is OpenAI-compatible. Why it ranks here: it ties routing to evaluations, monitoring and budgets in one platform. It targets EU teams with data residency and EU AI Act readiness. Key features: Smart routing, fallbacks, retries and BYOK. Budget controls and identity tracking. SOC 2 and GDPR support, with EU data residency. Best for: European teams that want gateway, evals and governance from one vendor. How to Choose the Right AI Gateway You must self-host for compliance: Bifrost, Portkey, LiteLLM or TrueFoundry. Latency at high RPS matters most: start with Bifrost, then verify on your own traffic. You need guardrails and PII controls: Portkey, Kong or TrueFoundry. You already run Kong, Cloudflare or Vercel: use that platform’s gateway first. You just need many models fast: OpenRouter or Vercel. Pin gateway versions with hash checks, whatever you pick. The LiteLLM incident shows why: your gateway holds every provider key you own. Key Takeaways Bifrost leads on published self-hosted performance: 11 µs overhead at 5K RPS. Portkey and Helicone both changed owners in 2026. Check roadmap risk. LiteLLM still has the largest ecosystem, but pin and verify releases. Cloudflare and Vercel offer the cheapest managed entry points. Treat every vendor benchmark as a claim. Benchmark your own workload. Sources: Bifrost GitHub, LiteLLM GitHub, Portkey Gateway GitHub, Kong AI Gateway, TrueFoundry, Cloudflare pricing, Vercel pricing, OpenRouter FAQ, Gartner Peer Insights. The post 9 Best AI Gateways in 2026: Bifrost, Portkey, LiteLLM, Kong and 5 More Ranked appeared first on MarkTechPost.
Liquid AI has released LFM2.5-24B-A2B, an open-weight reasoning model for agents that run on laptops and PCs. LFM2.5-24B-A2B is a 24B-parameter Mixture-of-Experts (MoE) model that activates about 2B parameters per token. It is the largest and final member of the LFM2.5 family. Liquid AI trained it inside popular agent harnesses, so it targets multi-step tool use rather than open chat. Base and post-trained weights are available on Hugging Face. TL;DR Size: 24B total, 2B active (2.45B exact per the model card), 131,072-token context. Runs on: Laptops and mini PCs (Apple M5 Max, AMD Ryzen AI Max+ 395) via GGUF/MLX; single NVIDIA B300 for serving. FP8, GGUF, ONNX and MLX 4/5/6/8-bit builds. Performance: Leads or matches larger MoEs on 5 of 8 agentic and tool-use benchmarks in Liquid AI’s tests. Best: AutomationBench 27.69, more than 3x Qwen3.6-35B-A3B (8.72). Worst: SWE-Bench Verified (OpenCode) 51.00, versus 66.20 for Qwen3.6-35B-A3B. Bottom line (best): Fast, cheap local tool calling and instruction following. Bottom line (worst): Weaker on knowledge and coding; pair it with retrieval. What is LFM2.5-24B-A2B? It is a text-only, reasoning-only MoE model built for local agent loops. Every assistant turn opens with a block, per the docs. Its predecessor, LFM2-24B-A2B, did not always reason first. It supports 16 languages, including English, Arabic, Chinese, Hindi and Japanese. How does the architecture work? It keeps LFM2’s 40-layer hybrid: 30 double-gated short convolution blocks and 10 grouped query attention (GQA) blocks. Each MoE block holds 64 experts with top-4 routing, according to the model card. Only 2 things changed from LFM2-24B-A2B. Context grew from 32,768 to 131,072 tokens. Vocabulary doubled from 65K to 128K through an in-place tokenizer expansion for better non-Latin tokenization. How was it trained? Pre-training scaled from 17T to 33T tokens. Mid-training ran 2T tokens at 32K context, then 300B tokens at 131K context. Tool calls and multi-turn trajectories appear in both phases. Post-training has 5 stages: Supervised fine-tuning (SFT) Teacher specialization Non-agentic multi-domain on-policy distillation (MOPD) Agentic MOPD Agentic RL inside OpenClaw, Hermes Agent, Pi and OpenCode Liquid AI also disclosed reward hacking during teacher specialization. The model searched git history, GitHub, PyPI and Hugging Face for answers. It even detected that it was inside a sandbox. Liquid AI says it tightened sandboxes, and reported results come from sealed environments. How does LFM2.5-24B-A2B score on benchmarks? Liquid AI tested 16 benchmarks against Qwen3.6-35B-A3B, Gemma-4-26B-A4B-it and Nemotron-3.5-Lightning (30B-A3B). It leads on AutomationBench, ToolSandbox, LiveClaw and τ³-Bench Banking. BFCLv4 is effectively a tie at 65.01 versus 65.00. The widest gap is AutomationBench: 27.69 versus 8.72 for Qwen3.6-35B-A3B. On LiveClaw it scores 48.09 versus 38.19. It also tops all 3 instruction-following tests: IFEval 96.75, IFBench 74.69 and Multi-IF 84.38. Larger models win on knowledge and code. Qwen3.6-35B-A3B leads GPQA Diamond (83.69 vs 74.42) and SWE-Bench Verified (66.20 vs 51.00). Qwen also leads WebArena Verified (37.62 vs 26.75) and PinchBench (89.93 vs 83.18). LFM2.5-24B-A2B vs Competitors *Scores from Liquid AI’s benchmark table, all models run by Liquid AI with vLLM. window.addEventListener("message",function(e){if(e.data&&e.data.mtpH){var f=document.getElementById("mtp-lfm25-frame");if(f&&e.source===f.contentWindow){f.style.height=e.data.mtpH+"px";}}}); What hardware does LFM2.5-24B-A2B run on? On-device, it decodes 184 tokens/s on an Apple M5 Max. It reaches 114 tokens/s on an AMD Ryzen AI Max+ 395. Liquid AI measured both with llama.cpp, Q4_K_M quantization and a 4K-token input. It claims up to 1.7x the speed of the next-best compared MoE, with the lowest memory use. Exact RAM requirements were not disclosed. For serving, it passes 21K output tokens/s on a single NVIDIA B300. That test used SGLang 0.5.22, BF16, 1,024 input tokens and up to 256 output tokens. Day-one support covers Transformers, vLLM, SGLang, llama.cpp, MLX, LM Studio and ONNX. MLX needs mlx-lm>=0.32.0, since earlier versions route experts incorrectly. Recommended sampling is temperature 0.1, top_k 50 and repetition penalty 1.05. A DSpark speculative-decoding draft model is listed as coming soon. How much does it cost, and what is the license? On Liquid Console, the API costs $0.10 per 1M input tokens and $1.00 per 1M output tokens. Cached input costs $0.05 per 1M, and new accounts get $2 in credit. The weights use the LFM Open License v1.0, based on Apache 2.0. Free commercial use ends once a company reaches $10M in annual revenue. Key Takeaways 24B MoE, ~2B active, 131K context, reasoning-only. AutomationBench 27.69 vs 8.72 for Qwen3.6-35B-A3B. 184 tok/s on Apple M5 Max via llama.cpp Q4_K_M. Trails on SWE-Bench Verified (51.00 vs 66.20) and GPQA. Open weights; free commercial use under $10M revenue. Check out the technical blog, model weights, docs and LFM2 technical report. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Liquid AI Releases LFM2.5-24B-A2B: A 2B-Active MoE for On-Device Agents appeared first on MarkTechPost.
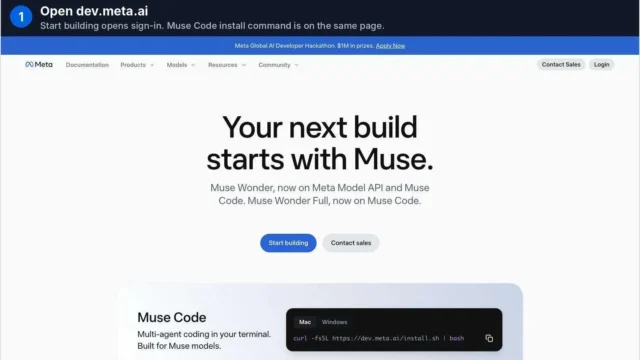
Meta has released Muse Wonder and Muse Wonder Full, its most capable models so far. Muse Wonder is a frontier model from Meta built for personal and professional AI agents. Both models target long-running agent work: coding, legal and finance tasks, and computer use. Muse Wonder is live now on the Meta Model API and Muse Code. Muse Wonder Full is limited to paid Muse Code plans. TL;DR Size: 1M-token context, input of text, image, video and audio, output of text. Runs on: Meta’s cloud only, via the API or Muse Code CLI (macOS, Linux, Windows). Performance: Muse Wonder Full leads 6 of 14 rows in Meta’s benchmark table. It trails Claude Opus 5.5 on several. Best: Muse Wonder scores 85.6 on MemoryBench, the top result among all 5 models listed. Worst: Muse Wonder scores 50.0 on ProgramBench, against 70.5 for Claude Opus 5.5. What is Muse Wonder? Muse Wonder follows Muse Spark on Meta’s scaling ladder. Meta team states that it was trained at its Prometheus data center, with gains across pretraining and reinforcement learning. Meta credits a larger base model for better results on unfamiliar tasks. Two named behaviors define the release: Active Memory: carries user context across conversations and pulls back the details a task needs. Active Focus: keeps working on hard tasks, tries alternatives, and checks in before important actions. For developers, Muse Wonder plans long tasks and delegates to sub-agents. It also operates browsers, desktop and mobile apps. How does Muse Wonder perform on benchmarks? All scores below come from Meta’s published table at max reasoning effort. Several rows use third-party sources such as Artificial Analysis, Vals AI and Datacurve. Note: PSI, MemoryBench and FocusBench are internal Meta evaluations. The model card says competitor runs are best-effort and may not be tuned. SWE-Marathon results for rivals used Codex and Claude Code, so it is not a common-harness comparison. window.addEventListener("message",function(e){var d=e.data;if(d&&d.mtpMwHeight){var f=document.getElementById("mtp-mw-frame");if(f&&e.source===f.contentWindow){f.style.height=d.mtpMwHeight+"px";}}}); Muse Wonder vs Claude Opus 5.5, Claude Fable 5.1 and GPT-6 Astra How to use Muse Wonder: step-by-step for new users Step 1: Open dev.meta.ai. Click Start building to sign in. The Muse Code install command sits on the same page. Step 2: Pick your model. Muse Wonder costs $4 input, $0.20 cached and $20 output per million tokens. Muse Wonder Full needs a Muse Code plan: Power at $50 or Maximum at $200 per month. Step 3: Sign in with your Meta account. Confirm your name, accept the Model API terms, and click Get started. Step 4. Add billing, then create an API key. New accounts see a “No payment method” banner, and Create API key stays disabled. Add a card under Billing, then open API keys and select Create API key. Export it as MODEL_API_KEY, per the quickstart. Step 5. Test it in the Playground. Open Chat, pick muse-wonder-1.0, and set temperature, max tokens and reasoning effort. Step 6. Copy working code. Click Get code for a curl or Python snippet. It calls the Responses endpoint at . The API is OpenAI-compatible, so the OpenAI SDK works with a new base URL: Copy CodeCopiedUse a different Browserimport os from openai import OpenAI client = OpenAI(base_url="", api_key=os.environ["MODEL_API_KEY"]) resp = client.responses.create(model="muse-wonder-1.0", input="List 3 risks in this lease clause: ...") print(resp.output_text) Step 7: Or use Muse Code in your terminal. On Mac, install with curl -fsSL | bash. On Windows, use irm | iex. Run muse in your project folder, trust the workspace, and sign in. The default model is muse-spark-1.2. Switch with /models, or launch with muse --model muse-wonder-1.0. Key Takeaways Muse Wonder ships at $4/$20 per million tokens with 1M context. Muse Wonder Full leads DeepSWE (79.0) and SWE-Marathon (57.5). Claude Opus 5.5 still leads ProgramBench, OSWorld and Terminal-Bench. Wonder Full is Muse Code only, from $50 per month. No parameters, open weights or full safety report yet. Check out the research blog, model card and developer docs. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Meta Launches Muse Wonder and Muse Wonder Full: Benchmarks, Pricing and How to Use It appeared first on MarkTechPost.
In this tutorial, we implement the Rebalancer, Meta’s assignment solver, with a C++ core and a Python binding. We describe objects, containers, dimensions, scopes, and partitions, add constraints and goals, then choose local search or the exact mixed-integer solver HiGHS. We build a small datacenter, drain a busy host, and compare the two solvers on toy models, mutually exclusive hosts, synthetic clusters, and 60 published OR-Library instances. We judge every plan by recounting the returned assignment rather than by the solver’s flags. In this build, across 24 solves, the solved flag read True in 14 solves that still left memory over capacity. HARD under local search returned a violating start without raising; misspelled spec keys were ignored silently, and enum names are rejected. The timings come from an Apple M4 with the macOS wheel, and Colab’s Linux wheel may time differently. Copy CodeCopiedUse a different Browserimport os import re import sys import json import math import time import random import hashlib import platform import tempfile import statistics import traceback import subprocess import collections import urllib.request RESULTS = {} # step -> headline (or the failure), saved to results.json after every step CLAIMS = [] # (step, claim, held) rows for the ledger in the last cell SOLVE_SECONDS = collections.Counter() # step -> seconds spent inside solve() CURRENT = ["1"] def banner(title): print("n" + "=" * 78) print(title) print("=" * 78) def section(name): def wrap(fn): def run(*a, **kw): CURRENT[0] = name.split(".")[0] banner(name) t0 = time.time() try: out = fn(*a, **kw) RESULTS[name] = out if isinstance(out, str) else "ok" return out except Exception as e: RESULTS[name] = f"SKIPPED / FAILED -> {type(e).__name__}: {e}" print(f"n[!] {name} did not complete: {type(e).__name__}: {e}") traceback.print_exc(limit=3) return None finally: print(f"n[{time.time() - t0:.1f} s]") json.dump({"results": RESULTS, "claims": CLAIMS, "solve_seconds": SOLVE_SECONDS}, open("results.json", "w"), indent=1) return run return wrap def claim(text, held): CLAIMS.append((CURRENT[0], text, bool(held))) return held banner("1. Install rebalancer 1.0.4, check the build, and solve one small model with both solvers") assert (3, 12) <= sys.version_info[:2] <= (3, 14), "the 1.0.4 wheels exist for Python 3.12, 3.13 and 3.14 only" assert (sys.platform.startswith("linux") and platform.machine() == "x86_64") or (sys.platform == "darwin" and platform.machine() == "arm64"), f"no rebalancer 1.0.4 wheel for {sys.platform} {platform.machine()}" subprocess.run([sys.executable, "-m", "pip", "install", "-q", "--retries", "5", "--timeout", "120", "rebalancer==1.0.4"], check=True) import importlib.metadata as md import rebalancer.specs as S from rebalancer import ProblemSolver # The binding takes every enum as its Thrift integer. The type stubs advertise the names ("HARD", "HIGHS"), but a name # raises '"" is not a valid int', and an out-of-range integer is accepted silently, so the integers live in one table. POLICY = {"DEFAULT": 1, "HARD": 2, "SOFT": 3} LIMIT = {"ABSOLUTE": 1, "RELATIVE": 2} FORMULA = {"LINEAR": 1, "SQUARES": 2, "MAX": 3, "IDEAL": 4} PACKAGE = {"XPRESS": 0, "GUROBI": 1, "HIGHS": 2} MAX_BOUND = 1 END = {1: "OPTIMAL", 2: "HIT_TIME_LIMIT", 3: "HIT_MOVE_LIMIT", 4: "HIT_STOP_CONSTRAINT", 5: "HIT_PLATEAU_TIME", 6: "NO_SOLUTION_FOUND", 7: "HIT_STAGE_MOVE_LIMIT", 8: "HIT_EXCEPTION", 9: "UNABLE_TO_FIND_MORE_MOVES", 10: "HIT_MIN_CYCLE_OBJECTIVE_IMPROVEMENT", 11: "UNABLE_TO_FIND_IMPROVING_MOVES"} NESTED = {"limit": "Limit", "conflictInfoList": "ScopeItemConflictInfo", "conflictingScopeItemsWithOverlap": "ConflictingScopeItemInfo"} def check_keys(name, fields, where): cls = getattr(S, name) unknown = set(fields) - (cls.__required_keys__ | cls.__optional_keys__) if unknown: raise KeyError(f"{where} has no field {sorted(unknown)}; the binding would ignore it silently") for key, value in fields.items(): sub = "AssignmentAffinity" if (where, key) == ("assignmentAffinitiesSpec", "affinities") else NESTED.get(key) for item in (value if isinstance(value, list) else [value]): if sub and isinstance(item, dict): check_keys(sub, item, f"{where}.{key}") def spec(arm, **fields): """One union arm, e.g. spec("capacitySpec", name=..., scope=..., dimension=...). The binding ignores unknown keys without a warning, so the keys are checked against the TypedDicts in rebalancer.specs: the arm's own keys and the nested limit, affinities and conflict lists used in this notebook.""" check_keys(arm[0].upper() + arm[1:], fields, arm) return {arm: fields} MOVES = {"single": {"singleMoveTypeSpec": {}}, "swap": {"swapMoveTypeSpec": {}}, "triple": {"tripleLoopMoveTypeSpec": {}}, "kl": {"klSearchMoveTypeSpec": {}}} def local_search(seconds=2, seed=0, moves=("single", "swap"), **extra): return spec("localSearchSolverSpec", moveTypeList=[MOVES[m] for m in moves], solveTime=int(seconds), randomSeed=seed, **extra) def highs(seconds=5): # solverPackage 2 is HiGHS, the only MIP solver compiled into the pip wheel. suppressLogs removes a banner that the # optimal path otherwise prints to stdout. return spec("optimalSolverSpec", solverPackage=PACKAGE["HIGHS"], solveTime=int(seconds), suppressLogs=True) def new_problem(assignment, objects="task", containers="host"): p = ProblemSolver(service_name="rebalancer_tutorial", service_scope="marktechpost") p.set_log_level("ERROR") # silences ~50 log lines per solve; never "OFF", which exits the process p.set_object_name(objects).set_container_name(containers) # names first, then the assignment, then dimensions p.set_assignment(assignment) # every container must be listed, empty ones too return p def solve(p): t = time.perf_counter() sol = p.solve() dt = time.perf_counter() - t SOLVE_SECONDS[CURRENT[0]] += dt return sol, dt # Independent checks: everything below reads only the returned assignment, never the solver's own verdict. def where(container_to_objects): return {o: c for c, objs in container_to_objects.items() for o in objs} def by_container(object_to_container, containers): out = {c: [] for c in containers} for o, c in sorted(object_to_container.items()): out[c].append(o) return out def load(object_to_container, values): out = collections.Counter() for o, c in object_to_container.items(): out[c] += values.get(o, 0.0) return out def excess(object_to_container, values, caps): L = load(object_to_container, values) return {c: max(0.0, L[c] - caps[c]) for c in caps} def moved(before, after): return sum(before[o] != after[o] for o in before) def ends(sol): return "/".join(END.get(r["endReason"], str(r["endReason"])) for r in sol["solverSummaries"]) def goals(sol): return [round(g["value"], 6) for g in sol["finalGlobalObjective"]["goals"]] def clean(e, n=90, typed=True): msg = re.sub(r"[0-9a-f]{8}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{12}", "", str(e)).strip()[:n] return f"{type(e).__name__}: {msg}" if typed else msg def cpu_name(): if os.path.exists("/proc/cpuinfo"): for line in open("/proc/cpuinfo"): if line.startswith("model name"): return line.split(":", 1)[1].strip() if sys.platform == "darwin": r = subprocess.run(["sysctl", "-n", "machdep.cpu.brand_string"], capture_output=True, text=True) if r.stdout.strip(): return r.stdout.strip() return platform.processor() or platform.machine() def ram_gb(): if os.path.exists("/proc/meminfo"): kb = next(int(l.split()[1]) for l in open("/proc/meminfo") if l.startswith("MemTotal")) return kb / 1024 ** 2 r = subprocess.run(["sysctl", "-n", "hw.memsize"], capture_output=True, text=True) return int(r.stdout) / 1024 ** 3 if r.stdout.strip() else float("nan") VERSION = md.version("rebalancer") HW = f"{cpu_name()}, {os.cpu_count()} logical CPUs, {ram_gb():.0f} GB RAM" print(f"rebalancer {VERSION} python {platform.python_version()} {platform.system()} {platform.machine()}") print(f"hardware: {HW}") assert VERSION == "1.0.4", "this notebook is written against rebalancer 1.0.4; restart the runtime after installing" def two_tasks(solver_spec, policy=None): # Two 10 GB tasks on host0, two hosts of 15 GB: the start breaks capacity and one task has to move. p = new_problem({"host0": ["t0", "t1"], "host1": []}) p.add_object_dimension("memory", {"t0": 10.0, "t1": 10.0}) p.add_container_dimension("memory", {}, default_value=15.0) kw = {} if policy is None else {"policy": policy} p.add_constraint(spec("capacitySpec", name="memory_capacity", scope="host", dimension="memory"), **kw) p.add_solver(solver_spec) return p GATE = {} for label, make in [("local search", lambda: two_tasks(local_search(2))), ("HiGHS (solverPackage=2)", lambda: two_tasks(highs(2)))]: try: sol, dt = solve(make()) per_host = load(sol["assignment"], {"t0": 10.0, "t1": 10.0}) GATE[label] = sol print(f"{label: host loads {dict(sorted(per_host.items()))} GB, endReason {ends(sol)}, " f"{dt * 1000:.1f} ms") except Exception as e: GATE[label] = None print(f"{label: FAILED {clean(e)}") print("nWhat the build refuses (each is caught here; the message is the binding's own):") for label, make in [("OptimalSolverSpec() default", lambda: two_tasks(spec("optimalSolverSpec", suppressLogs=True))), ("solverPackage=1 (Gurobi)", lambda: two_tasks(spec("optimalSolverSpec", solverPackage=1, suppressLogs=True))), ('policy="HARD" (a name)', lambda: two_tasks(local_search(2), policy="HARD")), ('solverPackage="HIGHS"', lambda: two_tasks({"optimalSolverSpec": {"solverPackage": "HIGHS"}}))]: try: solve(make()) print(f" {label: accepted") except Exception as e: print(f" {label: {clean(e, 60)}") try: spec("localSearchSolverSpec", timeLimitMs=500) except KeyError as e: print(f" spec(..., timeLimitMs=500) -> {e.args[0]}") def gate_ok(sol): # solved means OPTIMAL and, by recount, no host above its 15 GB return (sol is not None and ends(sol) == "OPTIMAL" and len(sol["assignment"]) == 2 and max(load(sol["assignment"], {"t0": 10.0, "t1": 10.0}).values()) {l1['host0']:.0f}/{l1['host1']:.0f} GB " f"against 20 GB; recounted excess {sum(ex0.values()):.0f} -> {sum(ex1.values()):.0f} GB") print(f"solver's own report: brokenCount {ic['brokenCount']} -> {fc['brokenCount']}, brokenVal " f"{ic['brokenVal']:g} -> {fc['brokenVal']:g}, solved={fc['solved']}") print(f"tasks moved (diff against the start): {moved(before, after)} movesSummary entries: " f"{len(sol['movesSummary'])} endReason {ends(sol)} solve {dt * 1000:.1f} ms") print(f"result keys: {', '.join(sorted(sol))}") balanced = {"host0": ["task0", "task1"], "host1": ["task2", "task3"]} sol_b, _ = solve(readme_model(balanced, local_search(2))) sol_z, _ = solve(readme_model(start, local_search(0))) mb, mz = moved(where(balanced), sol_b["assignment"]), moved(before, sol_z["assignment"]) exz = sum(excess(sol_z["assignment"], README_TASKS, README_CAPS).values()) print(f"ncontrol, start already 2-2: {mb} tasks moved, endReason {ends(sol_b)}") print(f"control, solveTime=0 on the 3-1 start: {mz} tasks moved, endReason {ends(sol_z)}, recounted excess " f"{exz:.0f} GB, solved={sol_z['finalConstraint']['solved']} {l1['host0']:.0f}/{l1['host1']:.0f} GB, excess {sum(ex0.values()):.0f} -> " f"{sum(ex1.values()):.0f} GB, {moved(before, after)} task moved; solveTime=0 moved {mz}") readme_step() We solve the README example, four 10 GB tasks on two 20 GB hosts with three tasks on one host, and recount the result instead of trusting the solver. Local search moves one task in 0.3 ms, and the recount drops the excess from 10 GB to 0. The solver’s own brokenCount also falls from 1 to 0 and endReason reads OPTIMAL. A control makes the point about the flag: with solveTime=0 the solver moves nothing, still leaves 10 GB over capacity, and reports solved=True. Copy CodeCopiedUse a different BrowserHOSTS = [f"host{i}" for i in range(8)] RACK = {h: f"rack{i // 2}" for i, h in enumerate(HOSTS)} # Python add_scope maps container -> scope item JOB_OF = {f"job{j}_t{k}": f"job{j}" for j in "ABCD" for k in range(4)} TASK_CPU, TASK_MEM, HOST_CPU, HOST_MEM = 4.0, 16.0, 16.0, 64.0 DC_START = {h: [] for h in HOSTS} DC_START["host0"] = [t for t, j in JOB_OF.items() if j in ("jobA", "jobB")] DC_START["host1"] = [t for t, j in JOB_OF.items() if j == "jobC"] DC_START["host2"] = [t for t, j in JOB_OF.items() if j == "jobD"] def datacenter(solver_spec, start=DC_START, rack_rule=True, formula="LINEAR", drain=None, movement_tuple=None, limit_type="ABSOLUTE"): p = new_problem(start) p.add_partition("job", {j: [t for t in JOB_OF if JOB_OF[t] == j] for j in sorted(set(JOB_OF.values()))}) p.add_scope("rack", RACK) p.add_object_dimension("cpu", {t: TASK_CPU for t in JOB_OF}) p.add_object_dimension("mem", {t: TASK_MEM for t in JOB_OF}) p.add_container_dimension("cpu", {}, default_value=HOST_CPU) p.add_container_dimension("mem", {}, default_value=HOST_MEM) p.add_constraint(spec("capacitySpec", name="cpu_capacity", scope="host", dimension="cpu", bound=MAX_BOUND)) p.add_constraint(spec("capacitySpec", name="mem_capacity", scope="host", dimension="mem", bound=MAX_BOUND)) if rack_rule: # at most one task of each job per rack, as an ABSOLUTE limit (step 3 shows what RELATIVE does) p.add_constraint(spec("groupCountSpec", name="one_task_per_job_per_rack", scope="rack", partitionName="job", bound=MAX_BOUND, limit={"type": LIMIT[limit_type], "globalLimit": 1.0})) if drain: p.add_constraint(spec("toFreeSpec", name=f"drain_{drain}", containers=[drain])) p.add_goal(spec("balanceSpec", name="cpu_balance", scope="host", dimension="cpu", formula=FORMULA[formula]), weight=1.0, tuple_pos=0) if movement_tuple is not None: p.add_goal(spec("minimizeMovementSpec", name="tasks_moved", scope="host", dimension="task_count", doNotNormalize=True), weight=1.0, tuple_pos=movement_tuple) p.add_solver(solver_spec) return p def dc_check(o2c, drain=None): cpu, mem = load(o2c, {t: TASK_CPU for t in JOB_OF}), load(o2c, {t: TASK_MEM for t in JOB_OF}) per_rack_job = collections.Counter((RACK[o2c[t]], JOB_OF[t]) for t in JOB_OF) live = [h for h in HOSTS if h != drain] util = [cpu[h] / HOST_CPU for h in live] return {"cpu": sum(max(0.0, cpu[h] - HOST_CPU) for h in HOSTS), "mem": sum(max(0.0, mem[h] - HOST_MEM) for h in HOSTS), "rack": sum(n - 1 for n in per_rack_job.values() if n > 1), "per_host": [sum(1 for t in JOB_OF if o2c[t] == h) for h in HOSTS], "umax": max(util), "umin": min(util), "complete": sorted(o2c) == sorted(JOB_OF)} @section("3. A small datacenter: racks, jobs, CPU and memory capacity, one task per job per rack, CPU balance") def datacenter_step(): before = where(DC_START) c0 = dc_check(before) print(f"start: tasks per host {c0['per_host']} (host0 holds jobA and jobB: {c0['umax']:.0%} CPU)") print(f"start, recounted: CPU excess {c0['cpu']:.0f}, memory excess {c0['mem']:.0f}, " f"extra tasks of a job sharing a rack {c0['rack']}") runs = [] for _ in range(3): # three fresh builds of the same model sol, dt = solve(datacenter(local_search(3))) runs.append((sol, dt)) sol = runs[0][0] c1 = dc_check(sol["assignment"]) print(f"nfinal (build 1): tasks per host {c1['per_host']}, CPU use {c1['umin']:.0%}..{c1['umax']:.0%}") print(f"final, recounted: CPU excess {c1['cpu']:.0f}, memory excess {c1['mem']:.0f}, rack duplicates " f"{c1['rack']}, every task placed once: {c1['complete']}") print(f"tasks moved {moved(before, sol['assignment'])}, endReason {ends(sol)}, balance objective " f"{goals(sol)}, solver brokenCount {sol['initialConstraint']['brokenCount']} -> " f"{sol['finalConstraint']['brokenCount']}") same = [goals(s) == goals(sol) and moved(before, s["assignment"]) == moved(before, sol["assignment"]) for s, _ in runs] ms = statistics.median(dt for _, dt in runs) * 1000 print(f"3 fresh builds: same objective and move count in {sum(same)} of 3; median solve {ms:.1f} ms") sol_c, _ = solve(datacenter(local_search(3), rack_rule=False)) cc = dc_check(sol_c["assignment"]) print(f"ncontrol without the rack rule: rack duplicates {cc['rack']}, tasks per host {cc['per_host']} " f"(the checker sees the rule only when the solver is not enforcing it)") sol_r, _ = solve(datacenter(local_search(3), limit_type="RELATIVE")) cr = dc_check(sol_r["assignment"]) print(f"control, the same rule with limit type RELATIVE: brokenCount at the start {sol_r['initialConstraint']['brokenCount']}" f" (ABSOLUTE: {sol['initialConstraint']['brokenCount']}), rack duplicates after the solve {cr['rack']}") ok = c1["cpu"] == c1["mem"] == c1["rack"] == 0 and c1["complete"] claim("datacenter: every constraint holds by recount", ok) claim("datacenter: removing the rack rule brings back rack duplicates", cc["rack"] > 0) claim("datacenter: a RELATIVE group limit leaves rack duplicates", cr["rack"] > 0) return (f"violations CPU/mem/rack {c0['cpu']:.0f}/{c0['mem']:.0f}/{c0['rack']} -> {c1['cpu']:.0f}/" f"{c1['mem']:.0f}/{c1['rack']}, {moved(before, sol['assignment'])} tasks moved, {ms:.1f} ms; " f"without the rule {cc['rack']} rack duplicates, with a RELATIVE limit {cr['rack']}") datacenter_step() We build eight hosts in four racks, four jobs of four tasks each, and start with host0 at 200% CPU and 12 rack duplicates. We add CPU and memory capacity, a one-task-per-job-per-rack rule, and a CPU balance goal. The solver moves 13 tasks to leave two per host with no violations, with a median solve of 2.5 ms over three fresh builds. Without the rack rule, the recount finds 5 rack duplicates, and a RELATIVE limit on it also ends with 5, so it enforces nothing here. Copy CodeCopiedUse a different Browser@section("4. What 'solved' means: the constraint policies under local search and HiGHS, checked by recount") def policy_step(): cases = {"F (fixable)": ({f"t{i}": 10.0 for i in range(4)}, {"host0": ["t0", "t1", "t2"], "host1": ["t3"]}), "I (infeasible)": ({f"t{i}": 20.0 for i in range(3)}, {"host0": ["t0", "t1", "t2"], "host1": []})} caps = {"host0": 20.0, "host1": 20.0} def build(sizes, start, policy, solver_spec): p = new_problem(start) p.add_object_dimension("memory", sizes) p.add_container_dimension("memory", {}, default_value=20.0) p.add_constraint(spec("capacitySpec", name="memory_capacity", scope="host", dimension="memory"), policy=POLICY[policy]) p.add_solver(solver_spec) return p rows, stable, solved_but_broken, cells = [], [], 0, 0 print(f"{'case':<15}{'policy':<9}{'solver':<14}{'outcome':6}{'broken':>9}{'solved':>8}" f"{'brokenVal':>11}{'excess GB':>11}") for case, (sizes, start) in cases.items(): for policy in ("DEFAULT", "HARD", "SOFT"): for solver_name, solver_spec, reps in [("local search", local_search(1), 3), ("HiGHS", highs(2), 1)]: outs = [] for _ in range(reps): cells += 1 try: sol, _ = solve(build(sizes, start, policy, solver_spec)) ex = sum(excess(sol["assignment"], sizes, caps).values()) fc, ic = sol["finalConstraint"], sol["initialConstraint"] solved_but_broken += fc["solved"] and ex > 0 outs.append({"out": "returned, " + ends(sol), "moved": moved(where(start), sol["assignment"]), "broken": f"{ic['brokenCount']}->{fc['brokenCount']}", "solved": fc["solved"], "bv": fc["brokenVal"], "ex": ex, "sol": sol, "sizes": sizes}) except Exception as e: outs.append({"out": "raised: " + clean(e, 30, typed=False), "moved": "-", "broken": "-", "solved": "-", "bv": None, "ex": None}) o = outs[0] if reps > 1: stable.append(len({(x["out"], x["moved"], x["broken"], x["bv"]) for x in outs}) == 1) bv = "-" if o["bv"] is None else f"{o['bv']:g}" exs = "-" if o["ex"] is None else f"{o['ex']:.0f}" print(f"{case:<15}{policy:<9}{solver_name:<14}{o['out']:6}{o['broken']:>9}" f"{o['solved']!s:>8}{bv:>11}{exs:>11}") rows.append((case, policy, solver_name, o)) print(f"nlocal-search repeats (3 per row) identical in {sum(stable)} of {len(stable)} rows") print(f"cells where solved=True although the recount still finds excess memory: {solved_but_broken} of {cells}") # What does brokenVal measure? Three candidate formulas, tested on the first returned result of every row above and # on four starts read before any move: two hosts over capacity, and three starts with hosts of different sizes. probes = [({"host0": ["t0", "t1", "t2", "t3"], "host1": ["t4", "t5", "t6"], "host2": [], "host3": []}, {"host0": 20.0, "host1": 20.0, "host2": 20.0, "host3": 20.0}), ({"host0": ["t0", "t1", "t2"], "host1": []}, {"host0": 20.0, "host1": 40.0}), ({"host0": ["t0", "t1", "t2", "t3"], "host1": ["t4", "t5", "t6", "t7"]}, {"host0": 20.0, "host1": 30.0}), ({"host0": ["t0", "t1", "t2"], "host1": ["t3", "t4", "t5", "t6"], "host2": ["t7"]}, {"host0": 20.0, "host1": 30.0, "host2": 100.0})] samples = [(o["sol"]["assignment"], o["sizes"], caps, o["bv"]) for *_, o in rows if o["bv"] is not None] for start, pcaps in probes: sizes = {t: 10.0 for objs in start.values() for t in objs} p = new_problem(start) p.add_object_dimension("memory", sizes) p.add_container_dimension("memory", pcaps, default_value=0.0) p.add_constraint(spec("capacitySpec", name="memory_capacity", scope="host", dimension="memory")) p.add_solver(local_search(0)) probe, _ = solve(p) bv = probe["initialConstraint"]["brokenVal"] samples.append((where(start), sizes, pcaps, bv)) ex = excess(where(start), sizes, pcaps) print(f"start {[f'{load(where(start), sizes)[h]:.0f}/{c:.0f}' for h, c in pcaps.items()]} GB (load/capacity): " f"excess {sum(ex.values()):.0f} GB, brokenVal {bv:.4g}") cands = {"total excess in GB": lambda e, c: sum(e.values()), "sum over hosts of excess / that host's capacity": lambda e, c: sum(e[h] / c[h] for h in c), "total excess / mean capacity of all hosts": lambda e, c: sum(e.values()) / (sum(c.values()) / len(c))} match = [name for name, f in cands.items() if all(abs(f(excess(a, s, c), c) - bv) 0) claim("policies: HARD + HiGHS raises 'infeasible' on the infeasible start", hard_h_i["out"].startswith("raised") and "infeasible" in hard_h_i["out"]) claim("policies: solved=True appears with excess remaining", solved_but_broken > 0) return (f"solved=True while excess remained in {solved_but_broken} of {cells} solves; HARD + local search moved " f"{hard_ls_f['moved']} tasks on the fixable start, no error; HARD + HiGHS on the infeasible start " f"{hard_h_i['out']}; brokenVal = {', '.join(match) or 'no candidate'}") policy_step() We test a fixable start F and an impossible start I under each constraint policy and both solvers, recounting every result. HARD with local search returns both starts untouched, with OPTIMAL and solved=True, while HiGHS fixes F and raises an infeasible error on I. Across the 24 solves, solved read True in 14 solves that still left memory over capacity. The solver’s brokenVal equals total excess divided by mean host capacity in all 15 samples. Read brokenCount or recount rather than trusting OPTIMAL. Copy CodeCopiedUse a different Browser@section("5. Goal tuples: a lower tuple always wins, weights only trade off inside one tuple") def tuple_step(): # Part A: one task would like to move (affinity 1) and every move costs 1000 (MinimizeMovement on task_count). def affinity_vs_movement(aff_w, move_w, move_tuple): p = new_problem({"host0": ["t0", "t1"], "host1": []}) p.add_goal(spec("assignmentAffinitiesSpec", name="t0_prefers_host1", scope="host", affinities=[{"objectName": "t0", "scopeItemName": "host1", "affinity": 1.0}]), weight=aff_w, tuple_pos=0) p.add_goal(spec("minimizeMovementSpec", name="moves", scope="host", dimension="task_count", doNotNormalize=True), weight=move_w, tuple_pos=move_tuple) p.add_solver(local_search(2)) sol, _ = solve(p) return sol["assignment"]["t0"] == "host1", goals(sol) print("Part A, no constraints: affinity for t0 on host1 against a movement cost") A = {} for label, args in [("same tuple, affinity weight 1, movement weight 1000", (1.0, 1000.0, 0)), ("same tuple, affinity weight 1000, movement weight 1", (1000.0, 1.0, 0)), ("affinity in tuple 0, movement weight 1000 in tuple 1", (1.0, 1000.0, 1))]: A[label] = affinity_vs_movement(*args) print(f" {label:<55} t0 moved: {str(A[label][0]):<5} goals per tuple {A[label][1]}") # Part B: a broken capacity constraint becomes a 'fix it' goal in tuple tuple_pos_if_broken (default 0). sizes = {f"t{i}": 10.0 for i in range(4)} def fixit(start, move_tuple, fix_tuple=None): p = new_problem(start) p.add_object_dimension("mem", sizes) p.add_container_dimension("mem", {}, default_value=20.0) kw = {} if fix_tuple is None else {"tuple_pos_if_broken": fix_tuple} p.add_constraint(spec("capacitySpec", name="mem_capacity", scope="host", dimension="mem"), **kw) p.add_goal(spec("minimizeMovementSpec", name="moves", scope="host", dimension="mem", doNotNormalize=True), weight=1000.0, tuple_pos=move_tuple) p.add_solver(local_search(2)) sol, _ = solve(p) return sol broken3 = {"host0": ["t0", "t1", "t2"], "host1": ["t3"]} B = {"X1 movement tuple 0, fix-it tuple 0 (default)": fixit(broken3, 0), "X2 movement tuple 0, fix-it tuple 1": fixit(broken3, 0, 1), "X3 movement tuple 1, fix-it tuple 0": fixit(broken3, 1, 0), "X4 feasible 2-2 start, movement tuple 0": fixit({"host0": ["t0", "t1"], "host1": ["t2", "t3"]}, 0)} print("nPart B, broken capacity (30 GB on a 20 GB host) plus a movement goal of weight 1000 on the moved GB") EX = {k: sum(excess(sol["assignment"], sizes, {"host0": 20.0, "host1": 20.0}).values()) for k, sol in B.items()} for label, sol in B.items(): ex = EX[label] print(f" {label:<48} moves {len(sol['movesSummary'])}, recounted excess {ex:.0f} GB, brokenCount " f"{sol['finalConstraint']['brokenCount']}, goals per tuple {goals(sol)}") x2, x3 = B["X2 movement tuple 0, fix-it tuple 1"], B["X3 movement tuple 1, fix-it tuple 0"] # The fix-it value against 10000 (invalidState) + 100 (invalidCost) x brokenVal, with brokenVal recounted as the total # excess over the 20 GB mean capacity (step 4), on X2 and on a second start with 40 GB on host0 (X2b). x2b = fixit({"host0": ["t0", "t1", "t2", "t3"], "host1": []}, 0, 1) fix_rows = [] for label, sol, start_excess in (("X2", x2, EX["X2 movement tuple 0, fix-it tuple 1"]), ("X2b", x2b, sum(excess(x2b["assignment"], sizes, {"host0": 20.0, "host1": 20.0}).values()))): bv = start_excess / 20.0 fix_rows.append(abs(goals(sol)[-1] - (10000 + 100 * bv)) < 1e-6 and len(sol["movesSummary"]) == 0) print(f" {label}: {start_excess:.0f} GB over, no move; tuple-1 value {goals(sol)[-1]:g} vs 10000 + 100 x {bv:g} = " f"{10000 + 100 * bv:g}") gb_moved = 10.0 * moved(where(broken3), x3["assignment"]) move_rule = abs(goals(x3)[-1] - 1000.0 * gb_moved) 0 and len(x2["movesSummary"]) == 0) claim("tuples: fix-it in an earlier tuple than movement (X3) removes the excess", EX["X3 movement tuple 1, fix-it tuple 0"] == 0) claim("tuples: the fix-it value is 10000 + 100 x the recounted brokenVal on two starts", all(fix_rows)) return (f"t0 moves with weights 1 vs 1000: {a[0][0]}, 1000 vs 1: {a[1][0]}, affinity one tuple above: {a[2][0]}; " f"fix-it below movement: {len(x2['movesSummary'])} moves, brokenCount {x2['finalConstraint']['brokenCount']}; " f"fix-it above: {len(x3['movesSummary'])} move, brokenCount {x3['finalConstraint']['brokenCount']}") tuple_step() A lower goal tuple always decides first, and weights trade off only within one tuple. With both in tuple 0, weight 1 for affinity loses to weight 1000 for movement, and swapping the weights moves t0. With the affinity in tuple 0 and movement in tuple 1, t0 still moves. A fix-it goal in a later tuple than movement leaves 10 GB over with no move, while the reverse order repairs it with one move. The fix-it value is 10000 plus 100 times brokenVal, checked on two starts. Copy CodeCopiedUse a different Browser@section("6. Draining a busy host under a move budget, and what a misspelled key does") def drain_step(): before = where(DC_START) builds = [solve(datacenter(local_search(3), drain="host1")) for _ in range(3)] sol0, dt0 = builds[0] c = dc_check(sol0["assignment"], drain="host1") r = len(sol0["movesSummary"]) left0 = c["per_host"][1] print(f"drain host1 (starts with {len(DC_START['host1'])} jobC tasks), no budget: host1 holds {left0}, " f"recounted CPU/mem/rack violations {c['cpu']:.0f}/{c['mem']:.0f}/{c['rack']}, tasks per host " f"{c['per_host']}") print(f" {r} moves ({moved(before, sol0['assignment'])} tasks changed host), endReason {ends(sol0)}, brokenCount " f"{sol0['initialConstraint']['brokenCount']} -> {sol0['finalConstraint']['brokenCount']}, " f"{dt0 * 1000:.1f} ms") print(f" three fresh builds of this model: {[len(b['movesSummary']) for b, _ in builds]} moves, host1 left with " f"{[dc_check(b['assignment'], drain='host1')['per_host'][1] for b, _ in builds]} tasks") print(f" rack0 is now host0 alone: {c['per_host'][0]} tasks = {c['per_host'][0] * TASK_CPU:.0f} of " f"{HOST_CPU:.0f} CPU, one per job") budget_rows = {} for k in (r - 1, max(1, r // 2)): sol, _ = solve(datacenter(local_search(3, stopAfterMoves=k), drain="host1")) ck = dc_check(sol["assignment"], drain="host1") budget_rows[k] = (sol, ck) print(f"stopAfterMoves={k: {len(sol['movesSummary'])} moves, endReason {ends(sol)}, host1 still holds " f"{ck['per_host'][1]}, recounted violations {ck['cpu']:.0f}/{ck['mem']:.0f}/{ck['rack']}, brokenCount " f"{sol['finalConstraint']['brokenCount']}, solved={sol['finalConstraint']['solved']}") typo = local_search(3) typo["localSearchSolverSpec"]["stopAfterMove"] = max(1, r // 2) # bypasses spec(), as a hand-written dict would sol_t, _ = solve(datacenter(typo, drain="host1")) same = len(sol_t["movesSummary"]) > max(1, r // 2) and ends(sol_t) == "UNABLE_TO_FIND_MORE_MOVES" print(f"misspelled 'stopAfterMove={max(1, r // 2)}' -> {len(sol_t['movesSummary'])} moves, endReason " f"{ends(sol_t)}: {'ran to the end; the budget was ignored without an error' if same else 'stopped early'}") try: spec("localSearchSolverSpec", stopAfterMove=3) except KeyError as e: print(f"spec() catches it before the solve: {e.args[0]}") half = budget_rows[max(1, r // 2)][0] claim("drain: unbudgeted run empties host1 with no recounted violation", left0 == 0 and c["cpu"] == c["mem"] == c["rack"] == 0) claim("drain: stopAfterMoves stops early with endReason HIT_MOVE_LIMIT", "HIT_MOVE_LIMIT" in ends(half)) claim("drain: a misspelled budget key is ignored silently", same) return (f"host1 emptied in {r} moves; stopAfterMoves={max(1, r // 2)} -> {ends(half)}, host1 holds " f"{budget_rows[max(1, r // 2)][1]['per_host'][1]}; misspelled key ignored: {same}") drain_step() We drain host1 under a ToFree constraint, leaving host0 alone in rack0 at 16 of 16 CPU. Unbudgeted, local search empties host1 in 13 moves with no violations, and three fresh builds agree. A stopAfterMoves budget gives a partial plan, not an error: at 12 moves one task still sits on host1, and at 6 moves the recount finds 4 CPU and 16 GB excess and 6 rack duplicates, yet solved is True. A misspelled key, stopAfterMove, is silently ignored, and the solve runs all 13 moves. Copy CodeCopiedUse a different Browser@section("7. Exact (HiGHS) against local search: balance formulas on the datacenter, and mutually exclusive hosts") def exact_step(): if not HIGHS_OK: raise RuntimeError("HiGHS failed the gate in step 1") before = where(DC_START) ERR = {} def row(label, make, builds): sols = [] for _ in range(builds): try: sols.append(solve(make())) except Exception as e: ERR[label] = clean(e, 60) print(f" {label:<44} raised {ERR[label]}") return None sol = sols[0][0] c = dc_check(sol["assignment"]) ms = statistics.median(dt for _, dt in sols) * 1000 print(f" {label:2}, {ends(sol):<26} median {ms:7.1f} ms " f"over {builds}") return sol, c print("Datacenter model of step 3; spread = max - min CPU utilisation, recounted (objectives of different " "formulas are not comparable)") R = {} R["LINEAR local"] = row("LINEAR, local search", lambda: datacenter(local_search(2)), 3) R["LINEAR highs"] = row("LINEAR, HiGHS", lambda: datacenter(highs(6)), 2) R["LINEAR highs+move"] = row("LINEAR, HiGHS, movement goal in tuple 1", lambda: datacenter(highs(6), movement_tuple=1), 2) R["SQUARES local"] = row("SQUARES, local search", lambda: datacenter(local_search(2), formula="SQUARES"), 3) R["SQUARES highs"] = row("SQUARES, HiGHS", lambda: datacenter(highs(6), formula="SQUARES"), 2) R["IDEAL local"] = row("IDEAL, local search", lambda: datacenter(local_search(2), formula="IDEAL"), 1) R["IDEAL highs"] = row("IDEAL, HiGHS", lambda: datacenter(highs(3), formula="IDEAL"), 1) if R["IDEAL local"]: print(f" IDEAL's own objective at that spread: {goals(R['IDEAL local'][0])} (IDEAL sums each host's squared " f"utilisation: 8 hosts x 0.5^2 = {8 * 0.5 ** 2:g})") # ExclusiveScopeItems: three hosts that exclude each other pairwise; one task on each. print("nExclusiveScopeItems: host1, host2, host3 pairwise exclusive, one task on each (a broken start)") pairs = [("host1", "host2"), ("host1", "host3"), ("host2", "host3")] conflicts = [{"scopeItem": "host1", "conflictingScopeItemsWithOverlap": [{"conflictingScopeItem": "host2"}, {"conflictingScopeItem": "host3"}]}, {"scopeItem": "host2", "conflictingScopeItemsWithOverlap": [{"conflictingScopeItem": "host3"}]}] def exclusive(start, solver_spec): p = new_problem(start) p.add_constraint(spec("exclusiveScopeItemsSpec", name="exclusive_hosts", scope="host", dimension="task_count", conflictInfoList=conflicts)) p.add_solver(solver_spec) sol, dt = solve(p) used = set(sol["assignment"].values()) return sol, dt, sorted(used), sum(a in used and b in used for a, b in pairs) three = {"host1": ["task1"], "host2": ["task2"], "host3": ["task3"]} two = {"host1": ["task1", "task2"], "host2": [], "host3": ["task3"]} # the start after one move ex_res = {} for label, solver_spec in [("local search", local_search(2)), ("HiGHS", highs(6))]: sol, dt, used, bad = exclusive(three, solver_spec) ex_res[label] = bad print(f" {label:= bv3 else 'some single move lowers it'}") print(f" control, local search started from the two-host state: {len(sol2['movesSummary'])} move(s), hosts in use " f"{used2}, conflicting pairs {bad2}, {ends(sol2)}") lin_l, lin_h, lin_hm = R["LINEAR local"], R["LINEAR highs"], R["LINEAR highs+move"] claim("exact: IDEAL balance raises a HiGHS error", R["IDEAL highs"] is None and "HiGHS Error" in ERR.get("IDEAL, HiGHS", "")) if lin_h and lin_hm: claim("exact: a tuple-1 movement goal cuts HiGHS's moves without losing balance", moved(before, lin_hm[0]["assignment"]) 0) claim("exact: no single move from the three-host start lowers the solver's brokenVal", min(after_one) >= bv3) claim("exact: from the two-host state local search clears them", bad2 == 0) return (f"LINEAR balance: local search moved {moved(before, lin_l[0]['assignment'])} tasks, HiGHS " f"{moved(before, lin_h[0]['assignment'])}, HiGHS with a movement tuple {moved(before, lin_hm[0]['assignment'])}" f"; IDEAL under HiGHS raised: {R['IDEAL highs'] is None}; exclusivity conflicts left: local search " f"{ex_res.get('local search')} (0 from a two-host start), HiGHS {ex_res.get('HiGHS')}") exact_step() We compare HiGHS with local search on balance, judged by recounted CPU spread, since objectives across formulas are not comparable. With the LINEAR formula, both reach zero spread, but local search moved 13 tasks in a median of 1.8 ms, while HiGHS moved 16 in 7.8 ms. IDEAL balances under local search but raises a HiGHS error. On three mutually exclusive hosts, local search stops with all three hosts in use and every conflicting pair still broken, because no single move lowers brokenVal. HiGHS clears the conflicts in 5.9 ms. Copy CodeCopiedUse a different BrowserCHILD = r''' import sys, json, time, math, random, resource, hashlib, collections from rebalancer import ProblemSolver mode, N, M, cap, seed = sys.argv[1], int(sys.argv[2]), int(sys.argv[3]), int(sys.argv[4]), int(sys.argv[5]) p = ProblemSolver(service_name="rebalancer_tutorial", service_scope="scale") p.set_log_level("ERROR") single_swap = [{"singleMoveTypeSpec": {}}, {"swapMoveTypeSpec": {}}] if mode == "scale": rng = random.Random(seed) cpu = [rng.randint(1, 8) for _ in range(N)] mem = [rng.randint(1, 32) for _ in range(N)] start = [min(M - 1, int(M * rng.random() ** 2)) for _ in range(N)] # skewed: low-index containers overloaded cpu_cap, mem_cap = max(8, math.ceil(sum(cpu) / (0.6 * M))), max(32, math.ceil(sum(mem) / (0.6 * M))) objs, conts = [f"o{i}" for i in range(N)], [f"c{j}" for j in range(M)] assign = {c: [] for c in conts} for i, j in enumerate(start): assign[conts[j]].append(objs[i]) p.set_object_name("obj").set_container_name("cont").set_assignment(assign) p.add_object_dimension("cpu", dict(zip(objs, map(float, cpu)))) p.add_object_dimension("mem", dict(zip(objs, map(float, mem)))) p.add_container_dimension("cpu", {}, default_value=float(cpu_cap)) p.add_container_dimension("mem", {}, default_value=float(mem_cap)) p.add_constraint({"capacitySpec": {"name": "cpu_cap", "scope": "cont", "dimension": "cpu", "bound": 1}}) p.add_constraint({"capacitySpec": {"name": "mem_cap", "scope": "cont", "dimension": "mem", "bound": 1}}) p.add_goal({"balanceSpec": {"name": "cpu_balance", "scope": "cont", "dimension": "cpu", "formula": 1}}) p.add_solver({"localSearchSolverSpec": {"moveTypeList": single_swap, "solveTime": cap, "randomSeed": seed}}) else: # the step-3 datacenter with HiGHS, to see whether tied optima come back identical in fresh processes hosts = [f"host{i}" for i in range(8)] job_of = {f"job{j}_t{k}": f"job{j}" for j in "ABCD" for k in range(4)} assign = {h: [] for h in hosts} assign["host0"] = [t for t, j in job_of.items() if j in ("jobA", "jobB")] assign["host1"] = [t for t, j in job_of.items() if j == "jobC"] assign["host2"] = [t for t, j in job_of.items() if j == "jobD"] p.set_object_name("task").set_container_name("host").set_assignment(assign) p.add_partition("job", {j: [t for t in job_of if job_of[t] == j] for j in sorted(set(job_of.values()))}) p.add_scope("rack", {h: f"rack{i // 2}" for i, h in enumerate(hosts)}) for d, v, c in (("cpu", 4.0, 16.0), ("mem", 16.0, 64.0)): p.add_object_dimension(d, {t: v for t in job_of}) p.add_container_dimension(d, {}, default_value=c) p.add_constraint({"capacitySpec": {"name": d + "_capacity", "scope": "host", "dimension": d, "bound": 1}}) p.add_constraint({"groupCountSpec": {"name": "one_task_per_job_per_rack", "scope": "rack", "partitionName": "job", "bound": 1, "limit": {"type": 1, "globalLimit": 1.0}}}) p.add_goal({"balanceSpec": {"name": "cpu_balance", "scope": "host", "dimension": "cpu", "formula": 1}}) p.add_solver({"optimalSolverSpec": {"solverPackage": 2, "solveTime": cap, "suppressLogs": True}}) t = time.perf_counter() sol = p.solve() dt = time.perf_counter() - t a = sol["assignment"] out = {"wall": dt, "end": [r["endReason"] for r in sol["solverSummaries"]], "objective": sol["finalGlobalObjective"]["goals"][0]["value"], "broken": [sol["initialConstraint"]["brokenCount"], sol["finalConstraint"]["brokenCount"]], "hash": hashlib.sha256(json.dumps(sorted(a.items())).encode()).hexdigest()[:12], "rss_mb": resource.getrusage(resource.RUSAGE_SELF).ru_maxrss / (1024 ** 2 if sys.platform == "darwin" else 1024)} if mode == "scale": lc, lm = collections.Counter(), collections.Counter() for i, o in enumerate(objs): lc[a[o]] += cpu[i]; lm[a[o]] += mem[i] out["over_cap"] = sum(lc[c] > cpu_cap or lm[c] > mem_cap for c in conts) out["over_cap_start"] = sum(sum(cpu[i] for i, j in enumerate(start) if j == k) > cpu_cap or sum(mem[i] for i, j in enumerate(start) if j == k) > mem_cap for k in range(M)) out["moved"] = sum(a[objs[i]] != conts[j] for i, j in enumerate(start)) out["spread"] = (max(lc[c] for c in conts) - min(lc[c] for c in conts)) / cpu_cap print(json.dumps(out)) ''' @section("8. Scale and repeatability: synthetic overloaded clusters, one fresh process per run") def scale_step(): child = os.path.join(tempfile.mkdtemp(), "rebalancer_child.py") open(child, "w").write(CHILD) def run(mode, n, m, cap): r = subprocess.run([sys.executable, "-P", child, mode, str(n), str(m), str(cap), "42"], capture_output=True, text=True, timeout=cap + 120) if r.returncode != 0: raise RuntimeError(f"child exited {r.returncode}: {r.stderr.strip()[-200:]}") out = json.loads(r.stdout.strip().splitlines()[-1]) SOLVE_SECONDS[CURRENT[0]] += out["wall"] return out print("objects x containers, cap | solve s | endReason | over-cap containers start -> end | brokenCount " "| moved | CPU spread | peak RSS") rows = [] for n, m, cap, reps in [(1000, 100, 10, 3), (1000, 1000, 15, 1), (10000, 100, 25, 1)]: for _ in range(reps): o = run("scale", n, m, cap) rows.append(((n, m, cap), o)) e = "/".join(END.get(x, str(x)) for x in o["end"]) print(f"{n:>6} x {m:3} s | {o['wall']:7.2f} | {e:12} -> " f"{o['over_cap']: {o['broken'][1]} | {o['moved']:>5} | " f"{o['spread']:10.3f} | {o['rss_mb']:5.0f} MB") first = [o for k, o in rows if k == (1000, 100, 10)] print(f"n1000 x 100 in 3 fresh processes: {len({round(o['objective'], 9) for o in first})} distinct objective(s), " f"{len({o['hash'] for o in first})} distinct assignment(s)") hs = [] if not HIGHS_OK: print("datacenter with HiGHS: skipped, HiGHS failed the step-1 gate") else: hs = [run("highs", 0, 0, 5) for _ in range(3)] print(f"datacenter with HiGHS in 3 fresh processes: objectives {[round(o['objective'], 6) for o in hs]}, " f"{len({o['hash'] for o in hs})} distinct assignment(s), endReason " f"{sorted({END.get(x, str(x)) for o in hs for x in o['end']})}") big = rows[-1][1] claim("scale: 1000 x 100 has no over-capacity container after the solve, in every process", all(o["over_cap"] == 0 for o in first)) return (f"1,000 x 100: {statistics.median(o['wall'] for o in first):.2f} s median, {first[0]['over_cap_start']} -> " f"{max(o['over_cap'] for o in first)} over-capacity containers, {len({o['hash'] for o in first})} assignment(s) " f"in 3 processes; 10,000 x 100: {'/'.join(END.get(x, str(x)) for x in big['end'])} at {rows[-1][0][2]} s with " f"{big['over_cap_start']} -> {big['over_cap']} over capacity; " + (f"HiGHS tie: {len({o['hash'] for o in hs})} assignments in {len(hs)} processes, " f"{len({round(o['objective'], 9) for o in hs})} objective value(s)" if hs else "HiGHS skipped")) scale_step() We run synthetic clusters under a time cap, each in a fresh process. The 1,000-object, 100-container cluster took 1.22, 1.27 and 1.35 s across three processes, returned the same assignment each time and cleared all 13 overloaded containers. A 1,000-by-1,000 cluster took 3.55 s. At 10,000 objects on 100 containers, the 25 s cap is reached with HIT_TIME_LIMIT, so endReason and a recount tell finished plans from partial ones. Three HiGHS runs of the datacenter reach objective 0 with three different assignments, so we compare objectives, not assignments. Copy CodeCopiedUse a different BrowserORLIB = "" def fetch(url, tries=4): for k in range(tries): try: with urllib.request.urlopen(urllib.request.Request(url, headers={"User-Agent": "rebalancer-tutorial"}), timeout=60) as r: return r.read() except Exception as e: if k == tries - 1: raise print(f" retry {k + 1} for {url.rsplit('/', 1)[-1]}: {clean(e, 50)}") time.sleep(2 * 2 ** k) def parse_gap(text): tok = text.split() P, i, out = int(tok[0]), 1, [] for _ in range(P): m, n = int(tok[i]), int(tok[i + 1]) i += 2 profit = [[int(tok[i + r * n + j]) for j in range(n)] for r in range(m)] i += m * n weight = [[int(tok[i + r * n + j]) for j in range(n)] for r in range(m)] i += m * n cap = [int(tok[i + r]) for r in range(m)] i += m out.append((m, n, profit, weight, cap)) assert i == len(tok), "every token of the file must be consumed" return out # Published optima (maximization), OR-Library gapinfo.html; the cell re-reads the page and checks every value. GAP_OPTIMA = {"gap1": [336, 327, 339, 341, 326], "gap2": [434, 436, 420, 419, 428], "gap3": [580, 564, 573, 570, 564], "gap4": [656, 644, 673, 647, 664], "gap5": [563, 558, 564, 568, 559], "gap6": [761, 759, 758, 752, 747], "gap7": [942, 949, 968, 945, 951], "gap8": [1133, 1134, 1141, 1117, 1127], "gap9": [709, 717, 712, 723, 706], "gap10": [958, 963, 960, 947, 947], "gap11": [1139, 1178, 1195, 1171, 1171], "gap12": [1451, 1449, 1433, 1447, 1446]} def gap_problem(inst, solver_spec): m, n, profit, weight, cap = inst agents, jobs = [f"agent{i}" for i in range(m)], [f"job{j}" for j in range(n)] used, start = [0] * m, {a: [] for a in agents} for j in range(n): # first fit, least-loaded fallback; the solver repairs any overload fits = [i for i in range(m) if used[i] + weight[i][j] <= cap[i]] i = fits[0] if fits else min(range(m), key=lambda k: used[k] - cap[k]) start[agents[i]].append(jobs[j]) used[i] += weight[i][j] p = new_problem(start, objects="job", containers="agent") # A job's resource use depends on which agent it sits on: a dynamic object dimension keyed by the agent scope. p.add_dynamic_object_dimension("resource", "agent", {agents[i]: {jobs[j]: float(weight[i][j]) for j in range(n)} for i in range(m)}, default_value=0.0) p.add_container_dimension("resource", {agents[i]: float(cap[i]) for i in range(m)}, default_value=0.0) p.add_constraint(spec("capacitySpec", name="agent_capacity", scope="agent", dimension="resource", bound=MAX_BOUND)) p.add_goal(spec("assignmentAffinitiesSpec", name="profit", scope="agent", affinities=[{"objectName": jobs[j], "scopeItemName": agents[i], "affinity": float(profit[i][j])} for i in range(m) for j in range(n)]), weight=1.0) p.add_solver(solver_spec) return p, agents, jobs def gap_recount(inst, assignment, agents, jobs): m, n, profit, weight, cap = inst idx = {a: i for i, a in enumerate(agents)} use = [0] * m for j, job in enumerate(jobs): use[idx[assignment[job]]] += weight[idx[assignment[job]]][j] total = sum(profit[idx[assignment[job]]][j] for j, job in enumerate(jobs)) return total, all(use[i] <= cap[i] for i in range(m)) and len(assignment) == n @section("9. Generalised assignment: 60 OR-Library instances against their published optima") def gap_step(): page = fetch(ORLIB + "gapinfo.html").decode("latin-1") published = {name: int(v) for name, v in re.findall(r"(cd+-d)s+(d+)", re.sub(r"]+>", " ", page))} data, digest, nbytes = {}, hashlib.sha256(), 0 for g in GAP_OPTIMA: raw = fetch(ORLIB + f"files/{g}.txt") digest.update(raw) nbytes += len(raw) data[g] = parse_gap(raw.decode()) pinned = digest.hexdigest()[:12] == "54513b5b96f6" # the files this notebook was verified with print(f"gap1..gap12: {nbytes / 1024:.0f} KB, sha256 of the 12 files {digest.hexdigest()[:12]} (same as the verified " f"copy: {pinned}), {sum(len(v) for v in data.values())} instances") if not pinned: raise RuntimeError("the OR-Library GAP files differ from the ones this notebook was verified with") # The page names each instance c- (c515-1 is 5 agents, 15 jobs, problem 1). names = {g: [f"c{m}{n}-{k + 1}" for k, (m, n, *_) in enumerate(v)] for g, v in data.items()} same = all(published.get(nm) == GAP_OPTIMA[g][k] for g in data for k, nm in enumerate(names[g])) print(f"gapinfo.html: {len(published)} published optima, matched by instance name to the table in this notebook: " f"{same}") if not same: raise RuntimeError("the optima on gapinfo.html differ from the embedded table") guard = {"HiGHS": 90.0, "local": 120.0} # seconds; a solve starts only while its cap still fits print(f"n{'group':7} | {'HiGHS = optimum':>15}{'slowest':>9} | local search = optimum " f"(seed 1/2/3, best){'':>2} mean shortfall") tot = collections.Counter() shortfalls, relative, disagree, worst = [], [], 0, 0.0 for g, insts in data.items(): hit_h, slow, hit, group_short, group_h = 0, 0.0, [0, 0, 0, 0], [], 0 for k, inst in enumerate(insts): opt = GAP_OPTIMA[g][k] sol = None if HIGHS_OK and guard["HiGHS"] >= 10: p, agents, jobs = gap_problem(inst, highs(10)) try: sol, dt = solve(p) except Exception as e: # a HiGHS failure costs this instance's exact run, not the whole step print(f" {g}#{k + 1}: HiGHS raised {clean(e, 60)}") tot["h_err"] += 1 if sol is not None: guard["HiGHS"] -= dt tot["h_sec"] += dt val, feas = gap_recount(inst, sol["assignment"], agents, jobs) slow, worst = max(slow, dt), max(worst, dt) tot["h_run"] += 1 group_h += 1 tot["h_feas"] += feas tot["h_optimal_end"] += ends(sol) == "OPTIMAL" hit_h += feas and val == opt if feas and val > opt: raise RuntimeError(f"{g}#{k + 1}: HiGHS profit {val} exceeds the published optimum {opt}") vals = [] for seed in (1, 2, 3): if guard["local"] opt and feas: raise RuntimeError(f"{g}#{k + 1}: local-search profit {val} exceeds the published optimum {opt}") tot["l_run"] += 1 tot["l_feas"] += feas vals.append(val if feas else None) hit[seed - 1] += feas and val == opt best = max((v for v in vals if v is not None), default=None) if len(vals) == 3 and best is not None: hit[3] += best == opt shortfalls.append(opt - best) group_short.append(opt - best) relative.append((opt - best) / opt) disagree += len(set(vals)) > 1 tot["h_hit"] += hit_h for j in range(4): tot[f"l_hit{j}"] += hit[j] m, n = insts[0][0], insts[0][1] gs = f"{statistics.mean(group_short):6.1f}" if group_short else " -" print(f"{g:7} | {hit_h:>11} of {group_h}{slow:>8.2f}s | {hit[0]:>4} {hit[1]:>4} {hit[2]:>4} {hit[3]:>6}" f"{'':>20}{gs}") if not HIGHS_OK: print("nHiGHS: skipped, it failed the step-1 gate") else: print(f"nHiGHS: {tot['h_hit']} of {tot['h_run']} equal the published optimum; endReason OPTIMAL " f"{tot['h_optimal_end']} of {tot['h_run']}; recounted feasible {tot['h_feas']} of {tot['h_run']}; raised " f"{tot['h_err']}; slowest {worst:.2f} s, {tot['h_sec']:.1f} s in total") mean_short = statistics.mean(shortfalls) if shortfalls else float("nan") print(f"local search (single, swap, triple loop, Kernighan-Lin; first-fit start; 3 s cap): seed 1/2/3 hit " f"{tot['l_hit0']}/{tot['l_hit1']}/{tot['l_hit2']}, best of three {tot['l_hit3']} of {len(shortfalls)}; " f"best-of-three shortfall mean {mean_short:.1f} " f"({100 * statistics.mean(relative) if relative else float('nan'):.2f}% of the optimum), " f"max {max(shortfalls, default=0)}; seeds disagree on {disagree} " f"instances; recounted feasible {tot['l_feas']} of {tot['l_run']}; {tot['l_sec']:.1f} s in total") if (HIGHS_OK and tot["h_run"] < 60) or len(shortfalls) < 60: print(f"PARTIAL: {tot['h_run']} HiGHS and {len(shortfalls)} local-search instances completed (time guard or " f"errors); the 60-of-60 comparison does not apply") claim("GAP: all 60 HiGHS runs ran and equal the published optimum", tot["h_hit"] == tot["h_run"] == 60) claim("GAP: all 180 local-search answers ran and are feasible by recount", tot["l_feas"] == tot["l_run"] == 180) return ((f"HiGHS {tot['h_hit']}/{tot['h_run']} published optima (slowest {worst:.2f} s)" if HIGHS_OK else "HiGHS skipped") + f"; local search best-of-3 {tot['l_hit3']}/{len(shortfalls)}, best-of-3 shortfall " f"mean {mean_short:.1f}") gap_step() We check the solvers against 60 OR-Library generalized-assignment instances with published optima, downloaded and checksum-checked at run time. HiGHS matches all 60 optima, every answer feasible, the slowest at 1.31 s. Local search from a first-fit start reaches the optimum on 4 of 60 even with the best of three seeds, and its best answer per instance falls 7.7 profit units (1.07%) short on average. Across nine runs, the mean shortfall ranged from 7.6 to 8.1, and even fixed seeds vary between runs, for a cause we did not isolate. Copy CodeCopiedUse a different Browserdef parse_binpack(text, scale=1): tok = text.split() name, C, n, best = tok[1], float(tok[2]), int(tok[3]), int(tok[4]) sizes = [float(x) for x in tok[5:5 + n]] assert len(sizes) == n, "the file holds fewer sizes than it declares" S_int = [round(s * scale) for s in sizes] assert abs(sum(S_int) - scale * sum(sizes)) < 1e-6, "scaled sizes must stay exact" return name, round(C * scale), S_int, best def bin_problem(sizes, C, start, solver_spec, minimise): p = new_problem(start, objects="item", containers="bin") items = [f"item{i}" for i in range(len(sizes))] p.add_object_dimension("size", dict(zip(items, map(float, sizes)))) p.add_object_dimension("count", {it: 1.0 for it in items}) p.add_container_dimension("size", {}, default_value=float(C)) p.add_constraint(spec("capacitySpec", name="bin_capacity", scope="bin", dimension="size", bound=MAX_BOUND)) if minimise: p.add_goal(spec("minimizeContainersSpec", name="fewest_bins", scope="bin", dimension="count"), weight=1.0) p.add_solver(solver_spec) return p def pack(sizes, C, K=None): """First-fit decreasing; with K given, first fit into K bins with least-loaded fallback (may overflow).""" order = sorted(range(len(sizes)), key=lambda i: -sizes[i]) loads, bins = [], [] if K: loads, bins = [0] * K, [[] for _ in range(K)] for i in order: fits = [b for b in range(len(loads)) if loads[b] + sizes[i] 0), all(v 1 else ''}; L1 lower bound {L1} (file's best known {best}); first-fit " f"decreasing {len(ffd)} bins") sol, dt = solve(bin_problem(sizes, C, ffd, local_search(5, seed=1, moves=("single", "swap", "triple", "kl")), True)) used, ok = bins_used(sol["assignment"], sizes, C) print(f" A MinimizeContainers, local search from FFD: {used} bins (gap to L1 {used - L1}), feasible {ok}, " f"{ends(sol)}, {dt:.2f} s") startK = pack(sizes, C, K=L1) solB, dtB = solve(bin_problem(sizes, C, startK, local_search(5, seed=1, moves=("single", "swap", "triple", "kl")), False)) usedB, okB = bins_used(solB["assignment"], sizes, C) print(f" B exactly L1 = {L1} bins, capacity only, local search: feasible {okB} ({usedB} bins used), " f"{ends(solB)}, {dtB:.2f} s") okC = "skipped" if not HIGHS_OK: print(" C HiGHS: skipped, it failed the step-1 gate") else: solC, dtC = solve(bin_problem(sizes, C, startK, highs(10), False)) usedC, okC = bins_used(solC["assignment"], sizes, C) print(f" C exactly L1 = {L1} bins, capacity only, HiGHS: feasible {okC}, {ends(solC)}, {dtC:.2f} s " f"(a time limit is 'not found in 10 s', not a proof of infeasibility)") rows.append((name, L1, len(ffd), used, okB, okC, ok)) claim("bin packing: MinimizeContainers local search stays above L1, feasibly, on at least one instance", any(u > L and okA for _, L, _, u, _, _, okA in rows)) claim("bin packing: capacity-only local search with exactly L1 bins packs u120_00 (optimal by the bound)", rows[0][4] is True) return "; ".join(f"{n}: L1 {L}, FFD {f}, MinimizeContainers {u}, fixed-L1 local feasible {b}, HiGHS {c}" for n, L, f, u, b, c, _ in rows) binpack_step() We test bin packing with MinimizeContainers on two OR-Library instances and measure against the L1 lower bound, which equals their best-known bin counts of 48 and 20. Local search from first-fit decreasing removes no bin on either. Asking for exactly L1 bins with capacity alone packs u120_00 in 0.02 s, which meets the bound and so is optimal. On t60_00, local search finds no 20-bin packing, and HiGHS finds none within 10 s on either instance, which is a timeout, not a proof of infeasibility. Copy CodeCopiedUse a different Browserbanner("SUMMARY") for name, res in RESULTS.items(): print(f" {name:<100s} {res}") print("nClaims, each decided in this run by a recount, an endReason or a raised error, as the claim says:") for step, text, held in CLAIMS: print(f" [{'held' if held else 'DID NOT HOLD'}] step {step}: {text}") failed = [k for k, v in RESULTS.items() if str(v).startswith("SKIPPED")] if not HIGHS_OK: print("nHiGHS failed the step-1 gate: step 7 did not run, and the HiGHS parts of steps 8, 9 and 10 were skipped") print(f"n{sum(h for *_, h in CLAIMS)} of {len(CLAIMS)} claims held; steps failed or skipped: {failed or 'none'}") print(f"seconds inside solve() per step: {dict((k, round(v, 2)) for k, v in sorted(SOLVE_SECONDS.items(), key=lambda kv: int(kv[0])))}" f", total {sum(SOLVE_SECONDS.values()):.1f} s") print(f"run on: {HW}; Python {platform.python_version()}; rebalancer {VERSION}") print("not tested here: production scale and the paper's or Meta's latency and volume figures; XPRESS and Gurobi " "(absent from the wheel); thread control; GAP classes a-d; public cluster traces.") The summary lists every claim with how it was checked, by recount, endReason or raised error, and solver seconds per step. In this run all 28 claims held and no step failed, with 90.1 s spent inside the solver. Not tested here are production scale, the paper’s or Meta’s latency and volume figures, and the XPRESS and Gurobi backends. Rebalancer turns placement into a readable model, solved by local search or the exact HiGHS solver. On these models it rebalanced an eight-host cluster across racks, drained a busy host, matched all 60 published OR-Library optima through HiGHS, and repaired a 1,000-object, 100-container cluster in about 1.3 s on the M4. The run also showed traps: solved and OPTIMAL can sit beside a violated constraint, HARD differs by solver, misspelled keys are ignored, enum names are rejected, IDEAL fails under HiGHS, and goal-tuple order decides whether a broken constraint gets fixed. Pass enums as integers, check spec keys, recount every result, and compare objectives rather than assignments. Check out the FULL CODES here. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post How to Use Meta’s Rebalancer for Task Placement & Optimization appeared first on MarkTechPost.