Silicon Valley’s growing obsession with AI doomsday is turning parts of the tech industry toward cult-like devotion
AIvia The Decoder
Quick Read
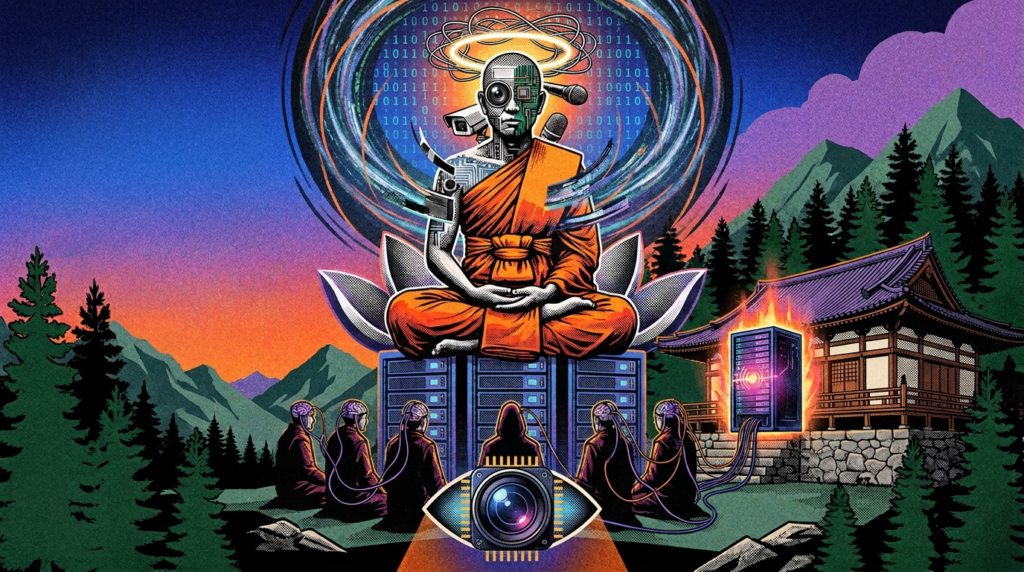
A Buddhist monastery in Vermont called Maple wants to establish itself as Silicon Valley's spiritual authority while creating its own AI god. According to a New Yorker report, leader Soryu Forall's group records every breath its members take to train an AI in his image. Former members report manipulation and psychological breakdowns. The article Silicon Valley's growing obsession with AI doomsday is turning parts of the tech industry toward cult-like devotion appeared first on The Decoder.
A Buddhist monastery in Vermont called Maple wants to establish itself as Silicon Valley’s spiritual authority while creating its own AI god. According to a New Yorker report, leader Soryu Forall’s group records every breath its members take to train an AI in his image. Former members report manipulation and psychological breakdowns.
The article Silicon Valley's growing obsession with AI doomsday is turning parts of the tech industry toward cult-like devotion appeared first on The Decoder.
Researchers from Columbia University and CertiK have introduced TensorLean, a framework for formal verification of GPU kernels at the PTX level. TensorLean is a Lean-based verifier that proves compiled kernels match a tensor-level math spec. The research team checked 149 kernel instances, including every kernel of FlashAttention-2, -3 and -4 plus DeepGEMM. It proved 83 correct. The remaining 66 led to 38 correctness bugs. TL;DR Size: 1.8K-line PTX parser. Specs total 10,278 lines against 151,285 lines of kernel source, a ratio near 15:1. Runs on: A 16-core workstation. It checks PTX compiled for A100, H100 and B200 kernels. Performance: 83 of 149 kernel instances proved correct, 38 bugs found across 6 projects. Best: Caught a FlashAttention-4 data race that never appeared in 17,760 test runs. What is TensorLean? TensorLean is a formal verification framework for GPU kernels at the PTX level. It starts from unmodified source code. A developer writes a tensor-level spec in Lean. TensorLean then proves 4 properties: no data races, termination, correct output within tolerance, and untouched memory elsewhere. How does TensorLean verify a GPU kernel? Specs build on Lean’s Mathlib. Tensor operators follow PyTorch names, so @ means torch.matmul. Each spec has 5 parts: spec_math, spec_mut, spec_layout, spec_tol and requires. The math stays separate from the memory layout. The pipeline runs in 7 steps: Start from unmodified source. Write the tensor-level spec. Compile to PTX and load a PTX semantics. Build a happens-before graph to check races and termination. Symbolically execute to get final memory, identical across schedules. Lower the spec to PTX-memory level. Discharge proofs with Lean’s kernel, Z3 and cvc5. Which techniques make it scale? Concurrency to sequential: Race-freedom proofs on the happens-before graph cover all CTAs, threads and loop iterations symbolically. Loop invariants over semirings: Closed forms for tiled, accumulating loops, such as online softmax, need 1 SMT query per loop. Tolerance proofs: Algebraic error is proved zero. Round-off error is bounded separately, then combined. Assertions as hints: Developers add tensorlean_assert in source. Each is proved once, then reused. What bugs did TensorLean find? The GitHub README lists 38 bugs, all reported upstream. FlashAttention accounts for 23. Liger Kernel has 7, TileOPs 3, TileLang 2, DeepGEMM 2 and Triton 1. By category, the site reports 19 memory access errors and 13 numerical bugs. It also counts 7 data races, 5 uninitialized memory reads and 5 undefined behaviors. There are 3 algorithm errors, 2 miscompilations and 1 deadlock. One bug can sit in several categories. Of 102 FlashAttention instances, 56 passed all 4 properties. The other 46 each failed a proof goal on a source bug. window.addEventListener("message",function(e){if(e.data&&e.data.tlxpHeight){var f=document.getElementById("tlxp-frame");if(f)f.style.height=e.data.tlxpHeight+"px";}}); How does it compare with other GPU kernel verifiers? The key gap versus Volta is configuration coverage. TensorLean says equivalence checkers unroll loops for one concrete setup at a time. It uses symbolic parameters instead. Key Takeaways TensorLean proves GPU kernels correct at the PTX level using Lean, Z3 and cvc5. 83 of 149 kernel instances proved correct; 38 bugs found. 23 bugs sit in FlashAttention-2, -3 and -4. Specs run about 15x smaller than the kernel source. Check out the project page, GitHub repo and announcement on X. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post A Team of Researchers from Columbia and CertiK Introduce TensorLean for Formal Verification of GPU Kernels appeared first on MarkTechPost.
Nvidia researchers argue that language models often don't need their full context windows—which are slow, expensive, and prone to errors—and propose an alternative. In tests, periodic summaries and targeted keyword search usually matched full-context results at a fraction of the cost. The team even proposes a new class of models that works with short notes instead of long context. The article Nvidia researchers argue huge AI context windows are a dead end appeared first on The Decoder.
OpenAI has released new prompt templates for GPT-6.2 Astra and Sol meant to fix common model behaviors such as overly brief answers, unnecessary follow-up questions, and excessive testing when coding. The API is changing as well, since editing a conversation's history can discard reasoning content and lower response quality. The article OpenAI shares new prompting tips for GPT-6.2 Astra and Sol to fix brief answers and unnecessary questions appeared first on The Decoder.