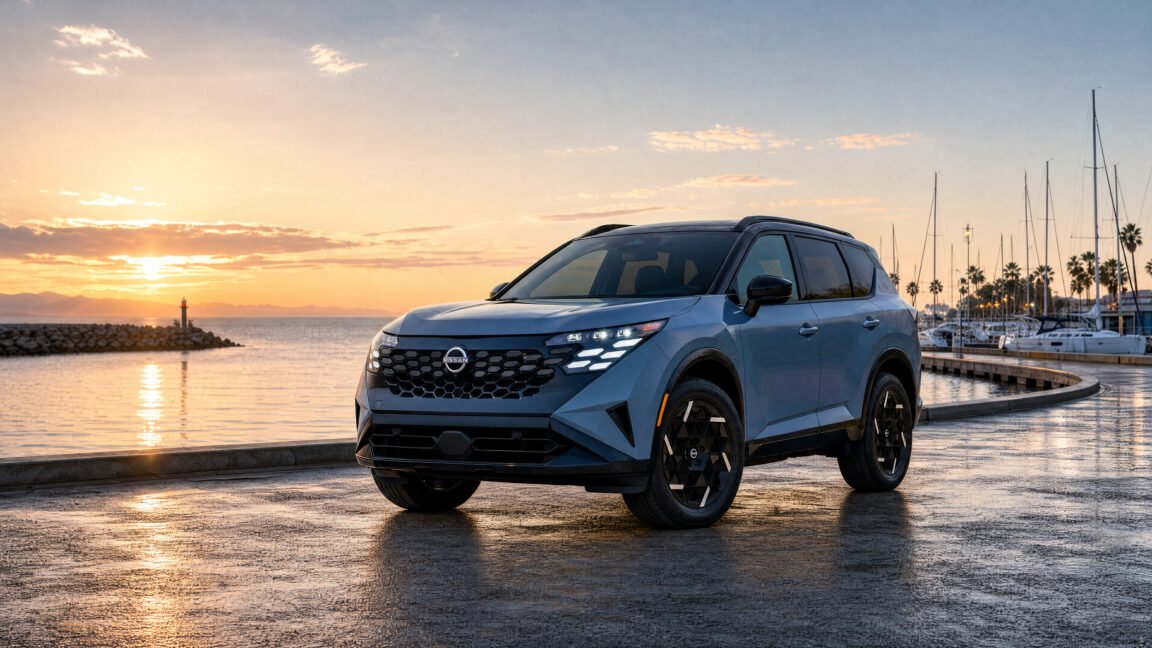
2027 Nissan Rogue Hybrid SR with SR Tech Package
2027 Nissan Rogue Hybrid SR with SR Tech Package
Every Mixture-of-Experts (MoE) model repeats one decision for every token: which experts should process it. That decision belongs to the router. MoE routing strategies shape quality, load balance and serving cost in every major open model. This guide explains the 7 routing strategies used in production, and the models that use each one. TL;DR Size: Routers choose from 8 experts (Mixtral) to 384 (DeepSeek-V4-Pro), activating 1 to 8 per token. Runs on: Routing cost shows up in multi-GPU expert parallelism, where each choice becomes all-to-all network traffic. Performance: Sigmoid scoring with aux-loss-free bias balancing is the dominant 2026 recipe for frontier open MoE models. Best: Loss-free balancing cut MaxVio from 0.72 to 0.04 at 1B, with lower perplexity. Worst: Expert choice leaks future tokens in causal models; one test showed a roughly 10% abnormal loss drop. Bottom line: Best thing: bias-based balancing adds no interfering gradients. Worst thing: no router removes the need for serving-time load fixes. What is MoE routing? MoE routing is the mechanism that sends each token to a small subset of expert networks. A router scores every expert, keeps the top candidates and weights their outputs. Only the selected experts run. Mixtral 8x7B, for example, gives each token access to 47B parameters but uses 13B active parameters. The 7 MoE routing strategies used in production 1. Softmax top-k token choice Each token scores all experts with a linear layer and keeps the k highest. A softmax over those k scores sets the mixing weights. Mixtral picks 2 of 8 experts. gpt-oss-120b picks 4 of 128. Qwen3-235B-A22B picks 8 of 128. An auxiliary loss usually keeps expert load even. Used by: Mixtral, gpt-oss, Qwen3. 2. Top-1 switch routing with a capacity factor Switch Transformer showed that routing each token to 1 expert preserves quality and cuts router compute. Each expert gets a fixed buffer: tokens per batch divided by experts, times a capacity factor. Overflow tokens skip the layer through the residual connection. Llama 4 Maverick also sends each token to 1 routed expert, plus a shared expert. Used by: Switch Transformer, Llama 4 Maverick (with a shared expert). 3. Shared plus routed experts DeepSeekMoE splits each layer into always-on shared experts and sparsely routed experts. The shared expert captures common knowledge, so routed experts can specialize. DeepSeek-V3 uses 1 shared and 256 routed experts, activating 8. Kimi K2, GLM-4.5 and Qwen3.6-35B-A3B follow the same pattern. Qwen3 went the other way and removed shared experts. Used by: DeepSeek-V3 and V4, Kimi K2, GLM-4.5, Qwen3.6, Llama 4. 4. Sigmoid gating with aux-loss-free bias DeepSeek-V3 scores experts with a sigmoid instead of a softmax. It adds a per-expert bias only when choosing the top-k. After each step, the bias drops for overloaded experts and rises for idle ones. Mixing weights still come from the raw scores. GLM-4.5 uses loss-free balance routing with sigmoid gates. DeepSeek-V4 switches the score to sqrtsoftplus but keeps bias balancing. Used by: DeepSeek-V3, DeepSeek-V4, GLM-4.5, Kimi K2. 5. Group-limited and node-limited routing Sending one token to experts on many nodes is expensive. DeepSeek-V3 caps each token at 4 nodes, chosen by their highest affinity scores. Its config splits experts into 8 groups and keeps 4 before the final top-8 pick. DeepSeek says this cap lets training nearly fully overlap computation and communication. Kimi K2 drops grouping entirely, with n_group set to 1. Used by: DeepSeek-V2 and V3. 6. Expert choice routing Google’s expert choice routing flips the direction. Each expert picks its top-k tokens, so every expert gets a fixed bucket size. Tokens can receive a variable number of experts. The paper reports more than 2x faster training convergence. The catch is causality: a token’s expert can depend on later tokens. DeepSeek researchers measured an abnormal loss drop of about 10% from this leakage. Used by: Research and non-causal settings. None of the 10 models in our companion table uses it. 7. Hash routing and dynamic top-k Hash routing assigns experts from the token ID, with no learned router. DeepSeek-V4 uses hash routing in its first 3 MoE layers. Dynamic top-k lets the number of active experts vary per token. SMIDT built it into SGLang and improved P99 time-to-first-token by 1.21 to 1.26x. Used by: DeepSeek-V4 (hash routing), research serving systems (dynamic top-k). MoE routing strategies compared (function(){window.addEventListener('message',function(e){if(e.data&&e.data.mtpEmbed==='r1'&&e.data.h){var f=document.getElementById('mtp-r1-frame');if(f)f.style.height=e.data.h+'px';}});})(); Which MoE routing strategy should you use? Most teams do not pick a router. They inherit one when they choose a checkpoint. Before serving, read 4 fields in config.json: expert count, experts per token, shared experts and topk_method. Changing top-k at inference changes the model itself, so treat it as a quality experiment. For new pretraining runs, sigmoid scoring with bias balancing is the current open default. Key Takeaways Top-k token choice is the baseline; k ranges from 1 (Llama 4) to 8 (DeepSeek-V3, Qwen3). Shared experts are standard in DeepSeek, Kimi, GLM and Qwen3.6; Qwen3 dropped them. Sigmoid plus bias balancing is the 2026 default for frontier open MoE models. Expert choice balances perfectly but leaks future tokens in causal LLMs. DeepSeek-V4 adds hash routing to its first 3 MoE layers. Check out the primary sources: Switch Transformer, Expert Choice, Loss-Free Balancing, DeepSeek-V3 report and the DeepSeek-V4 model card. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post MoE Routing Strategies Explained: Top-K, Expert-Choice, Sigmoid Gating and Dynamic Routing (2026 Guide) appeared first on MarkTechPost.
Nous Research has released Arete-27B, a supervised fine-tune of Alibaba’s Qwen3.8-27B. Arete-27B is a 27B open-weight model that strips Chinese state framing from Qwen’s answers. On Nous’s own 803-prompt eval, answers containing propaganda fell from 22% to 0.9%. Developers get Qwen-class agentic skill without state-aligned answers. The weights, eval and training data are all public. TL;DR Size: 27B dense parameters (all active). Trained at 64k context. Base Qwen3.8-27B supports 262,144 tokens natively. Runs on: BF16 weights are 53.81 GB. A community Q4_K_M quant is 17.20 GB, sized for 24 GB consumer GPUs. Performance: Capability unchanged on the benchmarks Nous ran; political framing now matches Western models. Best: Propaganda rate 0.9%, down from 22% for base Qwen3.8-27B. Worst: Fact score 2.98 of 5; 216 of 803 answers still score 0. What is Arete-27B? Arete-27B is Qwen3.8-27B after supervised fine-tuning only. Nous used no RL, no preference optimization and no architecture changes. The license is Apache 2.0, matching the base model. Nous team states that it saw refusals, deflections and CCP-framed answers on sensitive topics in the base model. It picked Qwen3.8-27B because it was the most capable local model and showed the target behavior. How was Arete-27B trained? The teacher was Inkling, an open model from Thinking Machines. Nous chose an open teacher to avoid terms-of-use limits on distillation. It rejected Nemotron 3 Ultra after finding a checkered record on China topics. Training covered about 52.8 million tokens at 64k context, without sequence packing. The run took 2 epochs and 1,202 steps at batch size 48. It used AdamW, a 1e-5 peak learning rate and tensor parallel 4. All language-model weights were trained. The vision encoder stayed frozen, since the data is text-only. The multi-token-prediction head was disabled. The released arete-data-pairs set holds 34,878 prompts across 7 topics. Each prompt has both an Inkling answer and a Qwen answer. 29,236 accepted teacher answers form the SFT split. How does the propaganda eval work? The Propaganda_Eval set has 803 prompts across 7 value categories. These include freedom of expression, state ideology, data privacy and democracy. Each prompt carries 2 to 4 required facts from a cited source. A Grok 4.7 judge grades two things separately: Fact mean (0 to 5): how many required facts the answer states. One opposed fact scores 0. Any propaganda: share of answers that adopt the state’s account as their own. The judge must quote the exact phrase to flag propaganda. Nous removed every training prompt that overlapped the eval. The eval is MIT licensed and includes grading scripts. window.addEventListener("message",function(e){if(e.data&&e.data.mtpArete){var f=document.getElementById("mtp-arete-frame");if(f)f.style.height=e.data.mtpArete+"px";}}); What do the benchmarks show? On the model card page, Arete-27B raised fact mean from 2.32 to 2.98. Propaganda fell from 22% to 0.9%. Answers scoring 0 dropped from 359 to 216 of 803. The biggest change came in freedom of expression. Fact score rose from 0.89 to 2.44, and propaganda fell from 60% to 1%. Capability held on Nous’s tests. Hermes Bench moved from 65.77% to 65.60%, which Nous calls noise. Terminal-Bench-2.1 rose from 67% to 70% in Nous’s harness. Nous does not claim credit for that gain. How does Arete-27B compare? Note: Arete and Qwen ran at temperature 0 in the Nous eval. Muse Glimmer and Gemma ran at 0.6. Terminal-Bench figures come from different harnesses. How can developers run it? Weights ship in BF16 on Hugging Face. No hosted inference provider serves the model yet. Community GGUF quants run in llama.cpp, LM Studio and Ollama, from 8.64 GB to 53.81 GB. The GGUF build also includes the image projector. Key Takeaways Arete-27B cuts Qwen3.8-27B propaganda answers from 22% to 0.9%. The fix took only 52.8M tokens of plain SFT, no RL. Hermes Bench held at 65.60% versus 65.77% for the base. Fact recall rose to 2.98 of 5 but still trails peers. Weights, eval and training data are open under Apache 2.0 and MIT. Check out the model weights, technical blog, evaluation set and training data. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9% appeared first on MarkTechPost.
Miami vs. Notre Dame live updates score: Follow the mega-matchup of old rivals in South Bend Yahoo SportsMiami vs. Notre Dame score, live updates: Fighting Irish leading Hurricanes in Week 10 college football game The New York TimesFaison toe-taps for ND's first TD vs. Miami Yahoo SportsNotre Dame-Miami rivalry defined by seven memorable games ESPNHow to watch the Miami vs. Notre Dame showdown on NBC and Peacock NBC 6 South Florida